AI Agent & Tool-Use Reliability AuditCorey Jacobs
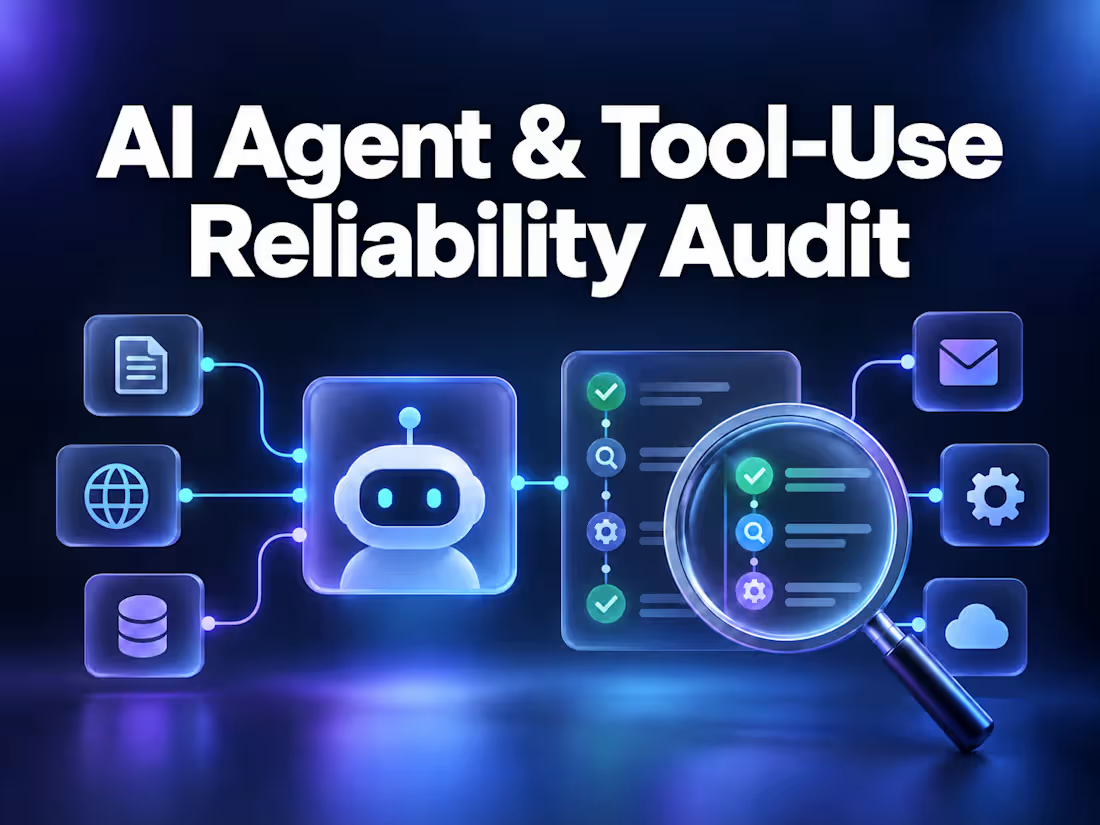
I test agents that call tools, APIs, MCP servers, browser actions, workflows, or other external systems — looking for the failures happy-path demos miss. I probe for incorrect tool selection, malformed tool calls, state loss, action/observation confusion, repeated actions, false claims that an action occurred, tool-result misinterpretation, permission and authority-boundary failures, recovery behavior, incomplete workflow execution, and evidence/receipt integrity. You receive adversarial scenarios, execution and failure traces where available, categorized findings, reproducible test cases, regression recommendations, and the evidence behind each classification. One fixed-price project. No invented metrics — every finding is backed by a trace you can inspect.
Example work
Corey's other services
Starting at$600
Duration2 weeks
Tags
Agent Testing
AI Evaluation
Service provided by
Corey Jacobs proSt Paul, USA
- 4
- Followers
AI Agent & Tool-Use Reliability AuditCorey Jacobs
Starting at$600
Duration2 weeks
Tags
Agent Testing
AI Evaluation
I test agents that call tools, APIs, MCP servers, browser actions, workflows, or other external systems — looking for the failures happy-path demos miss. I probe for incorrect tool selection, malformed tool calls, state loss, action/observation confusion, repeated actions, false claims that an action occurred, tool-result misinterpretation, permission and authority-boundary failures, recovery behavior, incomplete workflow execution, and evidence/receipt integrity. You receive adversarial scenarios, execution and failure traces where available, categorized findings, reproducible test cases, regression recommendations, and the evidence behind each classification. One fixed-price project. No invented metrics — every finding is backed by a trace you can inspect.
Example work
Corey's other services
$600