Website data scraping + clean datasetSheldon ZHUANG
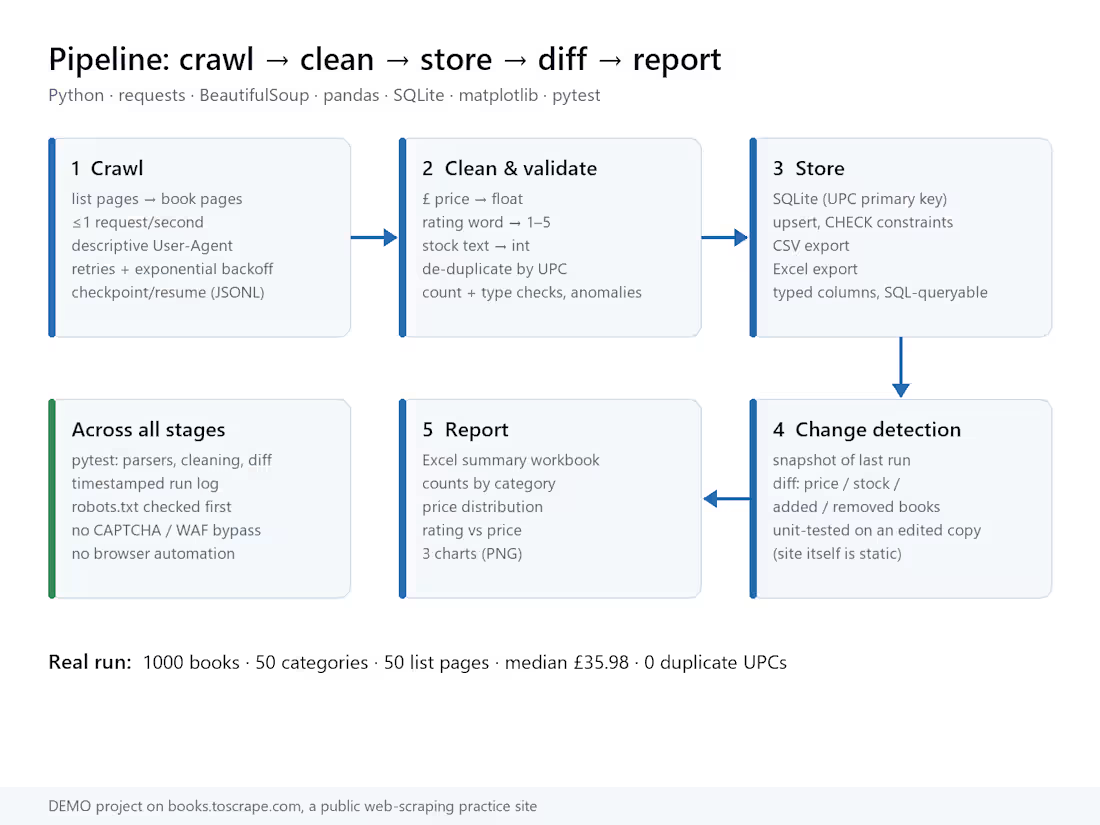
We collect public data from one website and hand it back clean: typed columns, no duplicates, and a short report on anything odd.
What you get (US$250)
- One public website, up to 5,000 rows and up to 10 fields, one run
- Clean data as CSV (UTF-8) and Excel: prices as numbers, dates as dates, duplicates removed by the key you choose
- An anomaly report: missing fields, outliers, our row count vs the count the site shows
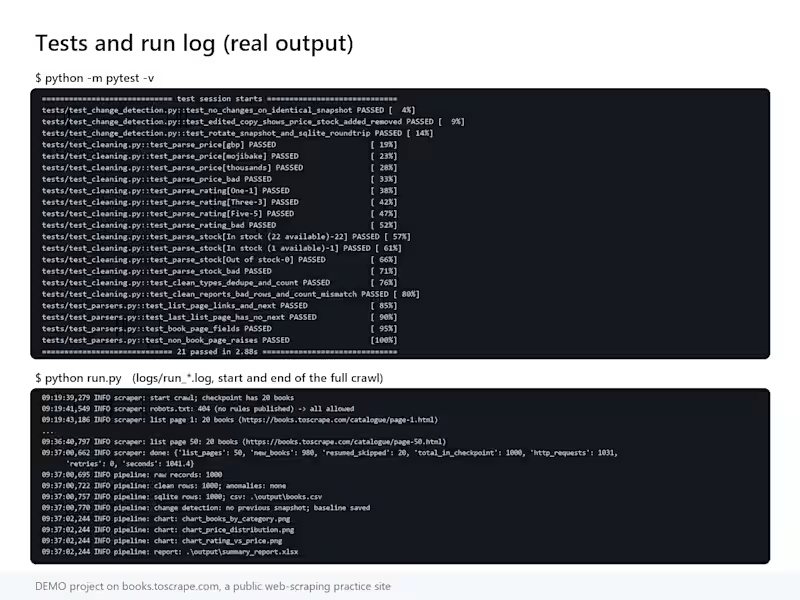
- The Python script, requirements file, README to rerun it, and the run log
Done means: every agreed field is present and typed, there are no duplicate keys, the row count matches the site (or the gap is explained in the report), and the script runs from the README on Python 3.11 or later.
Revisions: 1 round of fixes for anything that doesn't match the agreed field list. Extra rounds: US$60 each. New fields, new pages or a second site are a new request and are quoted first.
Timeline: 2 working days from the day the project is funded. If the URL, field list or answers to our questions arrive late, the delivery date moves by the same number of days.
Before you fund: send the URL and the fields you need. We check the site's terms and robots.txt first. If the site doesn't allow scraping, we tell you and you don't pay.
How we scrape: about 1 request per second, a clear User-Agent, plain HTTP.
Not included: sites behind a login, CAPTCHA or anti-bot bypass, proxies, personal data, sites that need a headless browser (quoted separately), more than 5,000 rows, scheduled reruns, hosting, and fixes after the site changes its layout.
Payment: the full amount is funded in Contra escrow before work starts. Contra's platform and payment fees are paid by the client. You get a 50-row sample and the row count first; the full dataset and the script are delivered after the payment is released.
Demo (practice site): https://github.com/SheldonZhuang/sheldontek-web-scraper-demo
SheldonTek
Sheldon's other services

Website data scraping + clean datasetSheldon ZHUANG
Starting at$250
Duration1 week
Tags
Python
We collect public data from one website and hand it back clean: typed columns, no duplicates, and a short report on anything odd.
What you get (US$250)
- One public website, up to 5,000 rows and up to 10 fields, one run
- Clean data as CSV (UTF-8) and Excel: prices as numbers, dates as dates, duplicates removed by the key you choose
- An anomaly report: missing fields, outliers, our row count vs the count the site shows
- The Python script, requirements file, README to rerun it, and the run log
Done means: every agreed field is present and typed, there are no duplicate keys, the row count matches the site (or the gap is explained in the report), and the script runs from the README on Python 3.11 or later.
Revisions: 1 round of fixes for anything that doesn't match the agreed field list. Extra rounds: US$60 each. New fields, new pages or a second site are a new request and are quoted first.
Timeline: 2 working days from the day the project is funded. If the URL, field list or answers to our questions arrive late, the delivery date moves by the same number of days.
Before you fund: send the URL and the fields you need. We check the site's terms and robots.txt first. If the site doesn't allow scraping, we tell you and you don't pay.
How we scrape: about 1 request per second, a clear User-Agent, plain HTTP.
Not included: sites behind a login, CAPTCHA or anti-bot bypass, proxies, personal data, sites that need a headless browser (quoted separately), more than 5,000 rows, scheduled reruns, hosting, and fixes after the site changes its layout.
Payment: the full amount is funded in Contra escrow before work starts. Contra's platform and payment fees are paid by the client. You get a 50-row sample and the row count first; the full dataset and the script are delivered after the payment is released.
Demo (practice site): https://github.com/SheldonZhuang/sheldontek-web-scraper-demo
SheldonTek
Sheldon's other services
$250