Data Annotation & Labeling for AI/ML Training DataInnerhouse Data
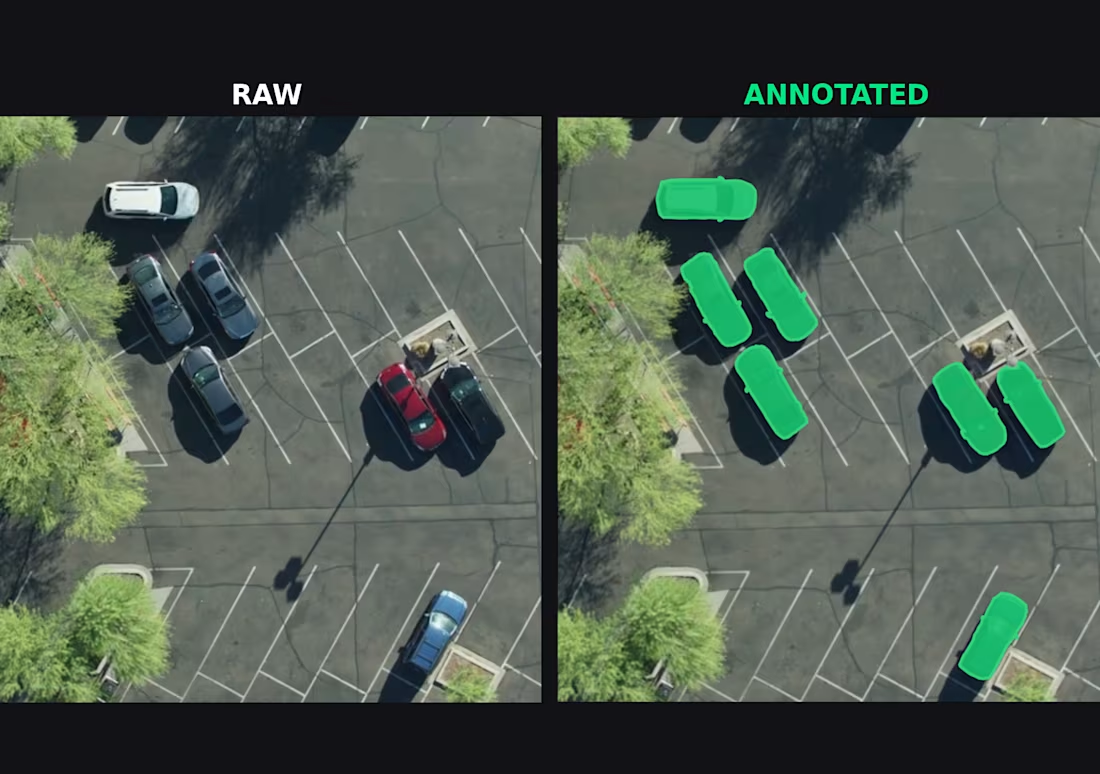
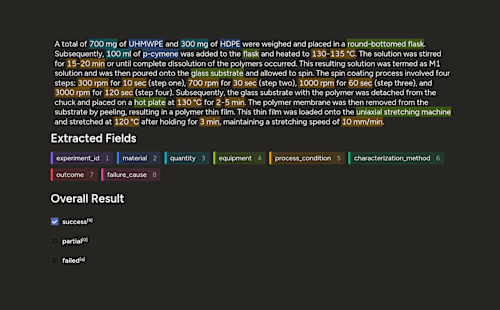
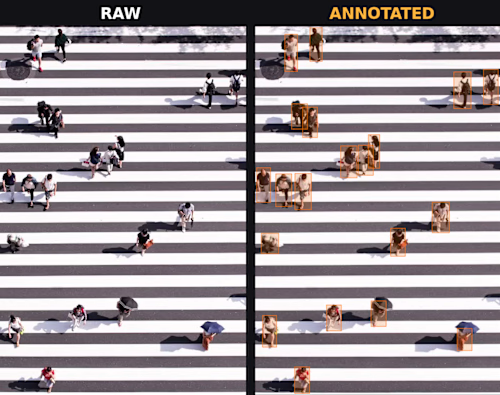
We provide accurate and consistent data annotation for AI and ML training pipelines such as image classification, object detection, bounding box annotation, text classification, and document/PDF extraction. Every batch goes through a dedicated QA pass before delivery, and we build the tagging schema around your specific classes and edge cases rather than forcing a generic template onto your data. Small, dedicated team, direct communication throughout the project, fast turnaround.
FAQs
Contact for pricing
Duration1 week
Tags
Data Annotation
Data Labeling
Bounding Box
Image Annotation
Image Classification
Object Detection
Text Annotation
Training Data
Video Annotation
Service provided by
Innerhouse Data United States
Data Annotation & Labeling for AI/ML Training DataInnerhouse Data
Contact for pricing
Duration1 week
Tags
Data Annotation
Data Labeling
Bounding Box
Image Annotation
Image Classification
Object Detection
Text Annotation
Training Data
Video Annotation
We provide accurate and consistent data annotation for AI and ML training pipelines such as image classification, object detection, bounding box annotation, text classification, and document/PDF extraction. Every batch goes through a dedicated QA pass before delivery, and we build the tagging schema around your specific classes and edge cases rather than forcing a generic template onto your data. Small, dedicated team, direct communication throughout the project, fast turnaround.
FAQs
Contact for pricing