Turnkey Private LLM Extraction PipelineBrandon Jenkins
Air-Gapped Document Extraction & Relational Pipeline.
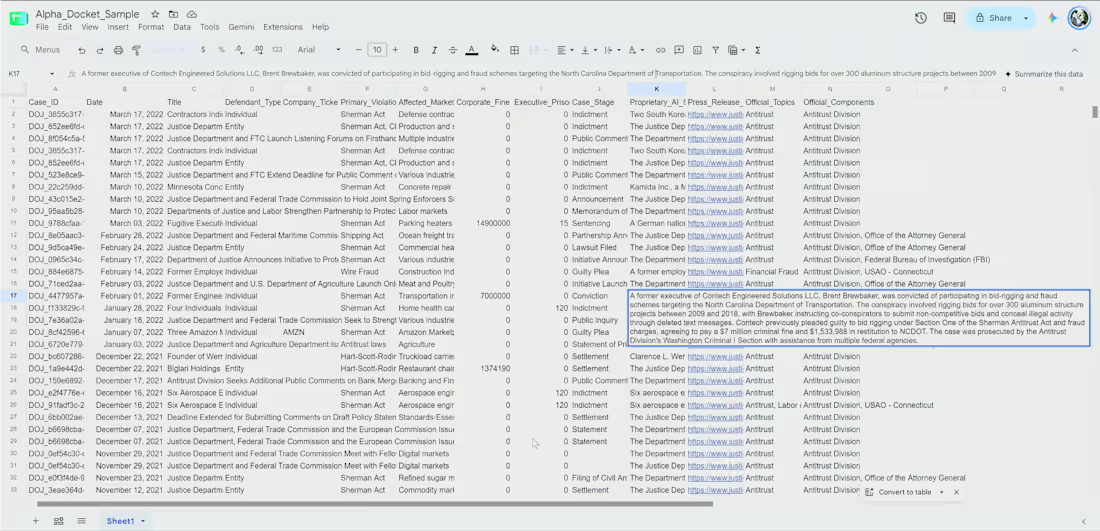
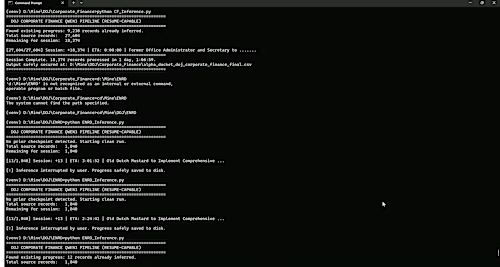
End-to-end ingestion and schema extraction using local models running on dedicated 24-core / RTX 3090 hardware—guaranteeing zero OpenAI API bills, zero rate limits, and 100% data privacy.
Custom Python extraction scripts, schema mapping (JSON/CSV/SQL), local inference execution, and post-processing validation.
Example work
Contact for pricing
Duration1 week
Tags
Clean Spreadsheets

Python
Data Analyst
Database Engineer
Data Scraper
Prompt Engineer
Artificial Intelligence
Service provided by
Brandon Jenkins Gladstone, USA
Turnkey Private LLM Extraction PipelineBrandon Jenkins
Contact for pricing
Duration1 week
Tags
Clean Spreadsheets
Python
Data Analyst
Database Engineer
Data Scraper
Prompt Engineer
Artificial Intelligence
Air-Gapped Document Extraction & Relational Pipeline.
End-to-end ingestion and schema extraction using local models running on dedicated 24-core / RTX 3090 hardware—guaranteeing zero OpenAI API bills, zero rate limits, and 100% data privacy.
Custom Python extraction scripts, schema mapping (JSON/CSV/SQL), local inference execution, and post-processing validation.
Example work
Contact for pricing