Optimize RAG Pipelines & Fix HallucinationsFakhreddine JADIB
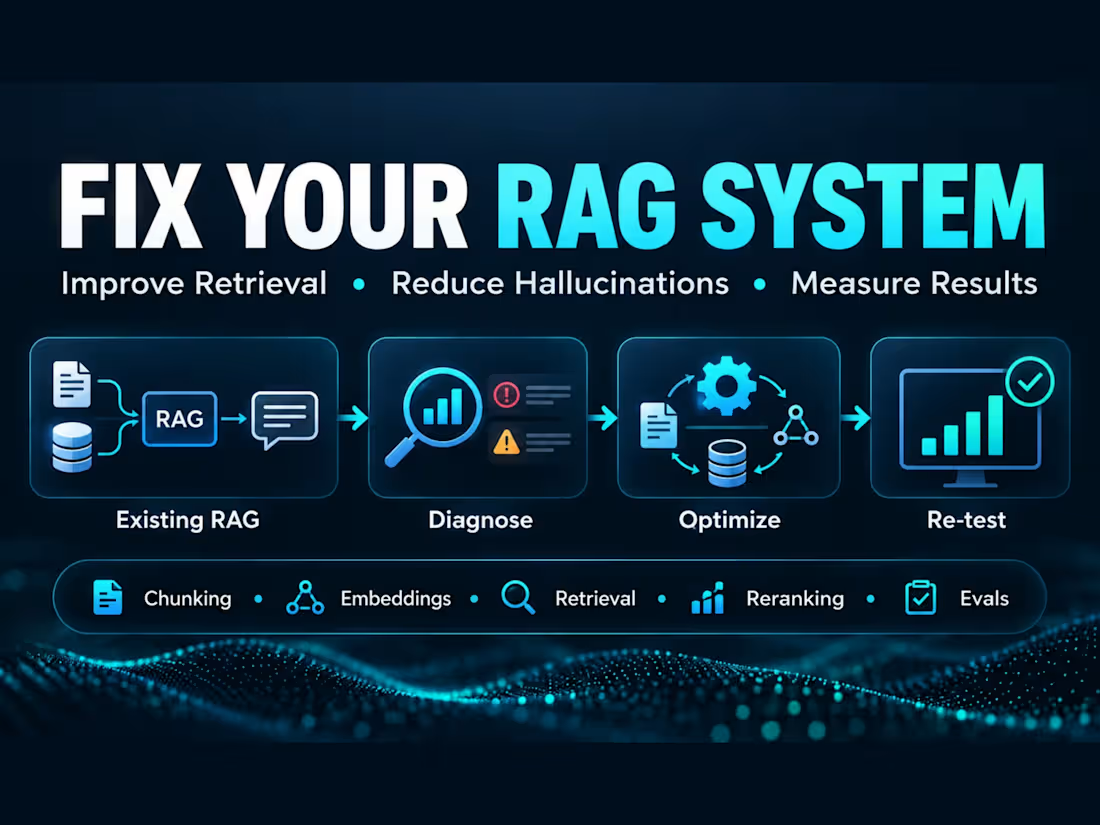
Stop LLM Hallucinations and Make Your RAG System Production-Ready
Building a basic Retrieval-Augmented Generation (RAG) prototype is easy, but scaling it into a reliable, production-ready AI application is incredibly challenging. If your AI chatbot or agent is ignoring context, providing irrelevant answers, or hallucinating facts, your pipeline needs expert optimization.
I specialize in diagnosing bottlenecks and debugging AI pipelines to ensure your Large Language Models (LLMs) stay grounded in your actual data. I will audit your current architecture and implement advanced techniques to drastically improve precision, recall, and answer relevance.
What I will do to optimize your system:
Advanced Chunking & Ingestion: I will fix poorly split documents by implementing semantic chunking strategies that preserve context, ensuring your Vector DB stores meaningful data.
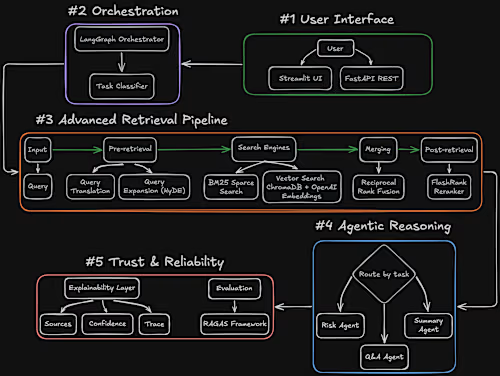
Retrieval Optimization: I will upgrade your search pipeline by implementing Hybrid Search (Keyword + Vector) and multi-stage retrieval with Cross-Encoder Re-ranking to surface only the most relevant context.
Prompt Engineering & Generation Tuning: I will refine your system prompts and implement strict context-window management so the LLM strictly adheres to retrieved facts and refuses to guess.
Evaluation & Metrics: I will implement evaluation frameworks (like RAGAS) to quantitatively measure your pipeline's accuracy, faithfulness, and answer relevance before and after optimization.
Tech Stack & Expertise:
LangChain, LlamaIndex, OpenAI, Anthropic, HuggingFace, Pinecone, Weaviate, ChromaDB, and Python.
Whether you need a quick technical audit or a complete pipeline overhaul, let's collaborate to build an AI system you and your users can actually trust. Send an inquiry to discuss your specific architecture!
FAQs
Contact for pricing
Tags
LangChain
Python
Vector Databases
Data Engineer
Machine Learning
Prompt Engineer
Software Architect
Artificial Intelligence
Large Language Models (LLMs)
Service provided by
Fakhreddine JADIB Casablanca, Morocco
- 4
- Followers
Optimize RAG Pipelines & Fix HallucinationsFakhreddine JADIB
Contact for pricing
Tags
LangChain
Python
Vector Databases
Data Engineer
Machine Learning
Prompt Engineer
Software Architect
Artificial Intelligence
Large Language Models (LLMs)
Stop LLM Hallucinations and Make Your RAG System Production-Ready
Building a basic Retrieval-Augmented Generation (RAG) prototype is easy, but scaling it into a reliable, production-ready AI application is incredibly challenging. If your AI chatbot or agent is ignoring context, providing irrelevant answers, or hallucinating facts, your pipeline needs expert optimization.
I specialize in diagnosing bottlenecks and debugging AI pipelines to ensure your Large Language Models (LLMs) stay grounded in your actual data. I will audit your current architecture and implement advanced techniques to drastically improve precision, recall, and answer relevance.
What I will do to optimize your system:
Advanced Chunking & Ingestion: I will fix poorly split documents by implementing semantic chunking strategies that preserve context, ensuring your Vector DB stores meaningful data.
Retrieval Optimization: I will upgrade your search pipeline by implementing Hybrid Search (Keyword + Vector) and multi-stage retrieval with Cross-Encoder Re-ranking to surface only the most relevant context.
Prompt Engineering & Generation Tuning: I will refine your system prompts and implement strict context-window management so the LLM strictly adheres to retrieved facts and refuses to guess.
Evaluation & Metrics: I will implement evaluation frameworks (like RAGAS) to quantitatively measure your pipeline's accuracy, faithfulness, and answer relevance before and after optimization.
Tech Stack & Expertise:
LangChain, LlamaIndex, OpenAI, Anthropic, HuggingFace, Pinecone, Weaviate, ChromaDB, and Python.
Whether you need a quick technical audit or a complete pipeline overhaul, let's collaborate to build an AI system you and your users can actually trust. Send an inquiry to discuss your specific architecture!
FAQs
Contact for pricing