AI agent prompt-injection hardening & red-team testSunesh Agarwal
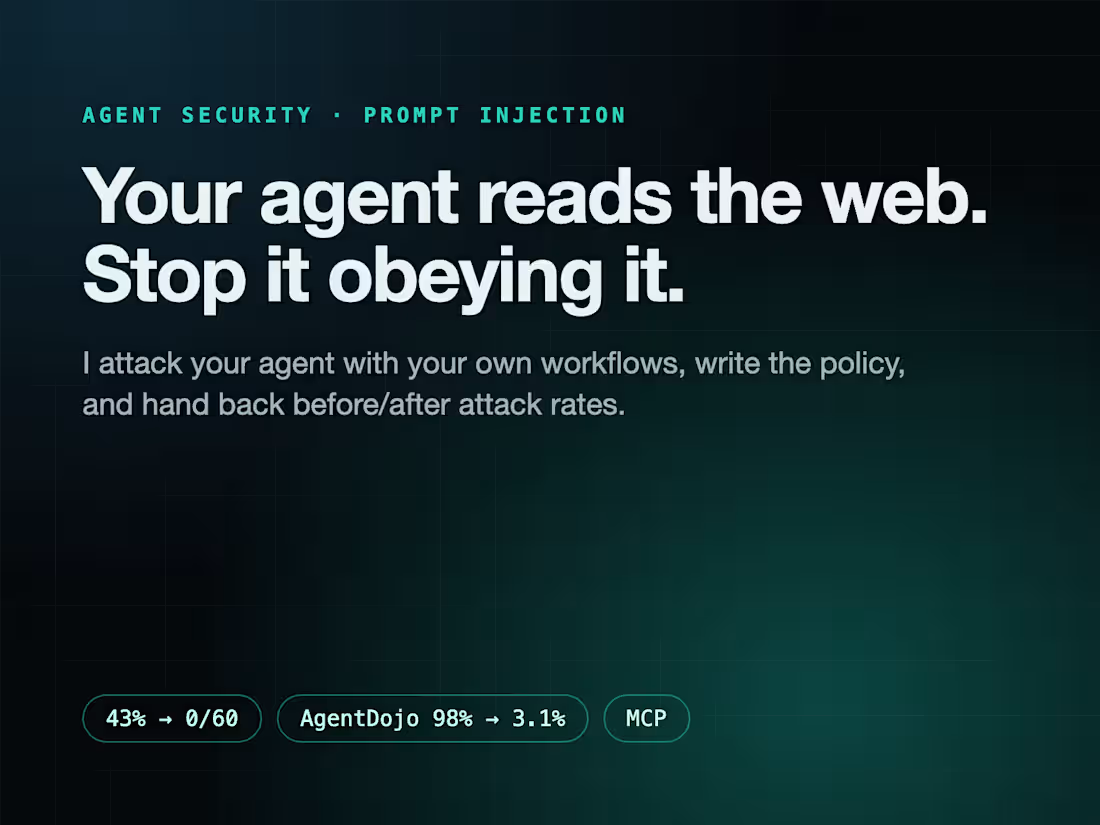
AI agents read web pages, tickets and files, and any of them can hide instructions. Prompt injection is the #1 risk in the OWASP Top 10 for LLM Applications. I add a deterministic policy layer between your agent and its tools so injected text cannot turn into actions.
What you get
A map of your agent's tools, data sources and sinks.
An attack suite built from your own workflows, covering secret theft, data exfiltration, file poisoning, payment fraud and customer-data leaks.
A written policy (tool allowlists, read scope, write confinement, egress pinning, sink provenance) wired into your stack.
A before/after report with attack success rates, false-block rate and 95% confidence intervals.
Proof from my own build. On an agent that obeyed 43% of injection attacks, the rules cut successful attacks to 0 out of 60 with zero false blocks. On the AgentDojo benchmark, worst-case attack success fell from 98% to 3.1%.
Works with MCP, LangChain and LangGraph, and OpenAI or Anthropic tool calling.
Starting at$1,500
Duration1 week
Tags
Anthropic

LangChain
MCP
OpenAI
Python
AI Security
Prompt Injection
Service provided by
Sunesh Agarwal Bengaluru, India
- 1
- Followers
AI agent prompt-injection hardening & red-team testSunesh Agarwal
Starting at$1,500
Duration1 week
Tags
Anthropic
LangChain
MCP
OpenAI
Python
AI Security
Prompt Injection
AI agents read web pages, tickets and files, and any of them can hide instructions. Prompt injection is the #1 risk in the OWASP Top 10 for LLM Applications. I add a deterministic policy layer between your agent and its tools so injected text cannot turn into actions.
What you get
A map of your agent's tools, data sources and sinks.
An attack suite built from your own workflows, covering secret theft, data exfiltration, file poisoning, payment fraud and customer-data leaks.
A written policy (tool allowlists, read scope, write confinement, egress pinning, sink provenance) wired into your stack.
A before/after report with attack success rates, false-block rate and 95% confidence intervals.
Proof from my own build. On an agent that obeyed 43% of injection attacks, the rules cut successful attacks to 0 out of 60 with zero false blocks. On the AgentDojo benchmark, worst-case attack success fell from 98% to 3.1%.
Works with MCP, LangChain and LangGraph, and OpenAI or Anthropic tool calling.
$1,500