LLM Evaluation & AI Agent Workflow ReviewAleksandr Gvozdkov
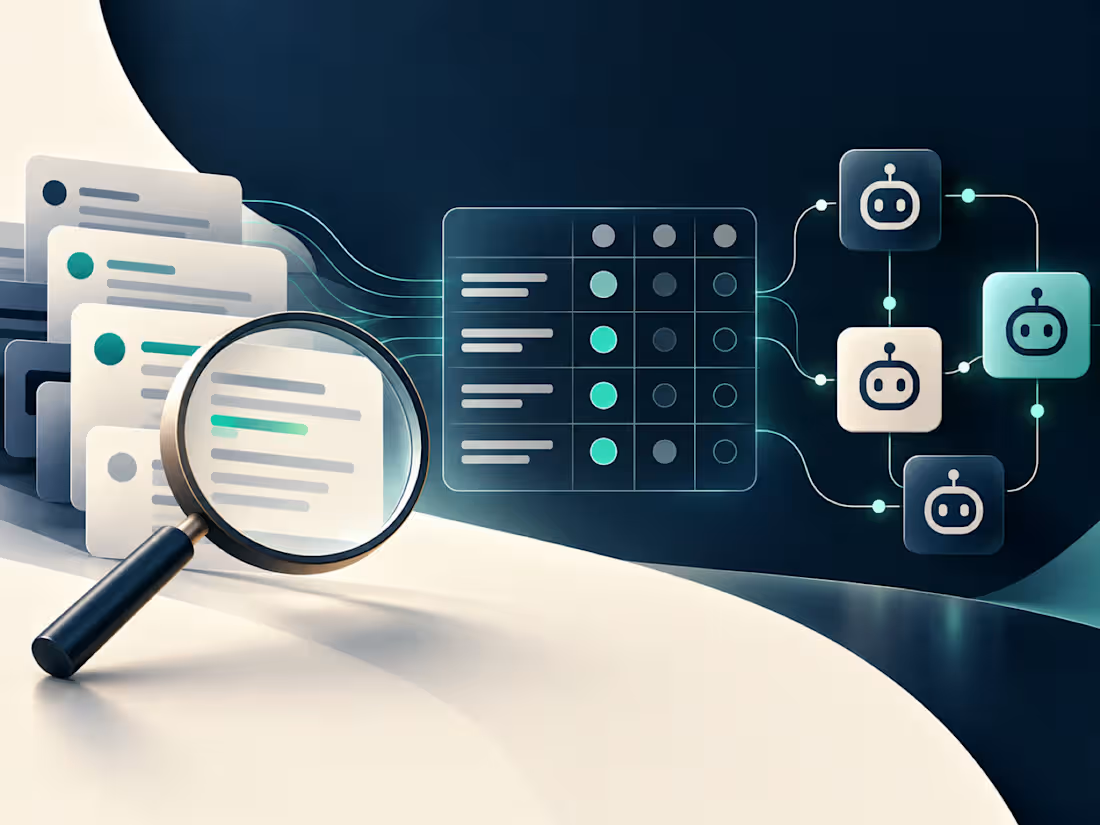
I review an LLM or AI-agent workflow and turn its failure patterns into a practical improvement plan.
You receive a written assessment of prompts, tool use, sample outputs, and evaluation criteria, with reproducible examples, prioritized issues, and recommendations for the next iteration. The standard scope is one workflow and up to 50 sample outputs, followed by a 30-minute handoff call.
Relevant experience: LLM response evaluation against structured rubrics, Python automation, LangGraph agent workflows, Claude API and MCP training. Share sanitized examples and a test environment; project scope and timeline are agreed before work begins.
FAQs
Aleksandr's other services
Contact for pricing
Duration1 week
Tags
AI Agents
LLM Evaluation
AI Developer
Service provided by
Aleksandr Gvozdkov New York, USA
- 1
- Followers
LLM Evaluation & AI Agent Workflow ReviewAleksandr Gvozdkov
Contact for pricing
Duration1 week
Tags
AI Agents
LLM Evaluation
AI Developer
I review an LLM or AI-agent workflow and turn its failure patterns into a practical improvement plan.
You receive a written assessment of prompts, tool use, sample outputs, and evaluation criteria, with reproducible examples, prioritized issues, and recommendations for the next iteration. The standard scope is one workflow and up to 50 sample outputs, followed by a 30-minute handoff call.
Relevant experience: LLM response evaluation against structured rubrics, Python automation, LangGraph agent workflows, Claude API and MCP training. Share sanitized examples and a test environment; project scope and timeline are agreed before work begins.
FAQs
Aleksandr's other services
Contact for pricing