LLM Evaluation, Prompt QA & Dataset AuditNaresh Kumar Pradhan
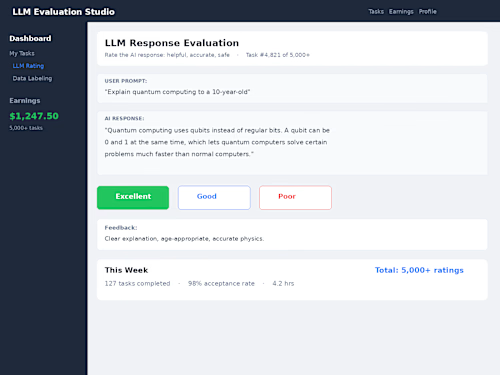
Ensure your AI application, RAG pipeline, or fine-tuning dataset delivers accurate, hallucination-free responses. Having evaluated 5,000+ model outputs at a 95%+ quality score, I provide rigorous human-in-the-loop QA combined with automated Python/Pandas validation checks.
What is included:
• Comprehensive evaluation and grading of up to 500 LLM prompt-response pairs or dataset rows
• Custom evaluation rubric covering factual grounding, instruction compliance, tone, and formatting constraints
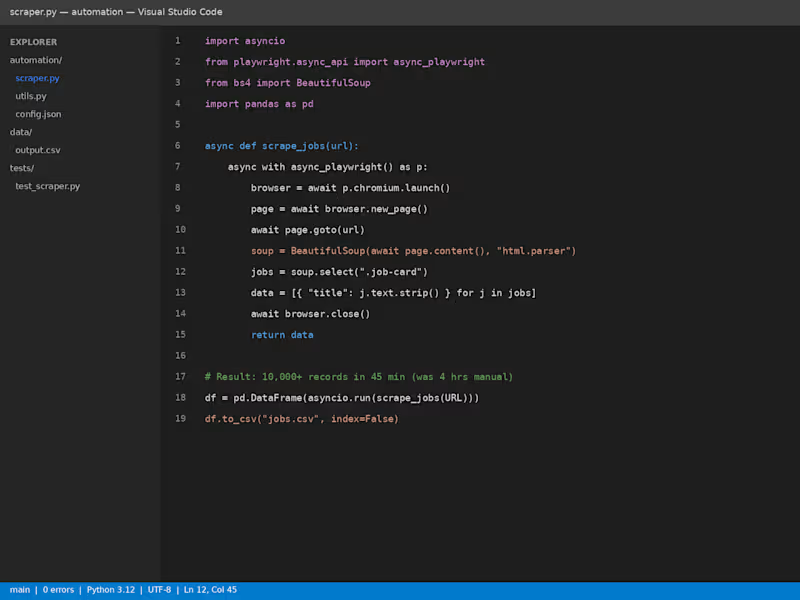
• Automated Python & Pandas quality gate script to catch schema errors, clichés, and edge-case failures
• Actionable failure-mode breakdown and prompt engineering optimizations to immediately improve model accuracy
FAQs
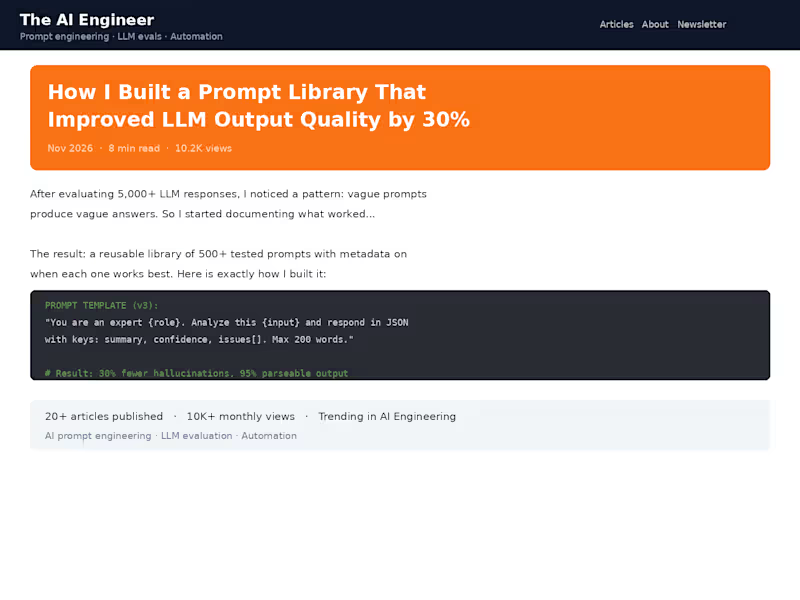
Example work
Starting at$250
Duration3 days
Tags
Claude
Data Analytics
OpenAI
Python
Data Scientist
Machine Learning
Prompt Engineer
Quality Assurance
Artificial Intelligence (AI)
Service provided by
Naresh Kumar Pradhan Brahmapur, India
- 2
- Followers
LLM Evaluation, Prompt QA & Dataset AuditNaresh Kumar Pradhan
Starting at$250
Duration3 days
Tags
Claude
Data Analytics
OpenAI
Python
Data Scientist
Machine Learning
Prompt Engineer
Quality Assurance
Artificial Intelligence (AI)
Ensure your AI application, RAG pipeline, or fine-tuning dataset delivers accurate, hallucination-free responses. Having evaluated 5,000+ model outputs at a 95%+ quality score, I provide rigorous human-in-the-loop QA combined with automated Python/Pandas validation checks.
What is included:
• Comprehensive evaluation and grading of up to 500 LLM prompt-response pairs or dataset rows
• Custom evaluation rubric covering factual grounding, instruction compliance, tone, and formatting constraints
• Automated Python & Pandas quality gate script to catch schema errors, clichés, and edge-case failures
• Actionable failure-mode breakdown and prompt engineering optimizations to immediately improve model accuracy
FAQs
Example work
$250