Open-Weight AI Model Deployment & API SetupUgo Chukwu
Deploy Your Own AI Model. Own Your Infrastructure.
Get an open-weight AI model deployed, configured, and accessible through a secure API—without managing the deployment complexity yourself.
Through DomainOS Managed Inference, I help companies and developers deploy models such as Qwen, Llama, and other supported open-weight LLMs on their own GPU or cloud infrastructure.
Your infrastructure. Your model configuration. Your control.
What's Included
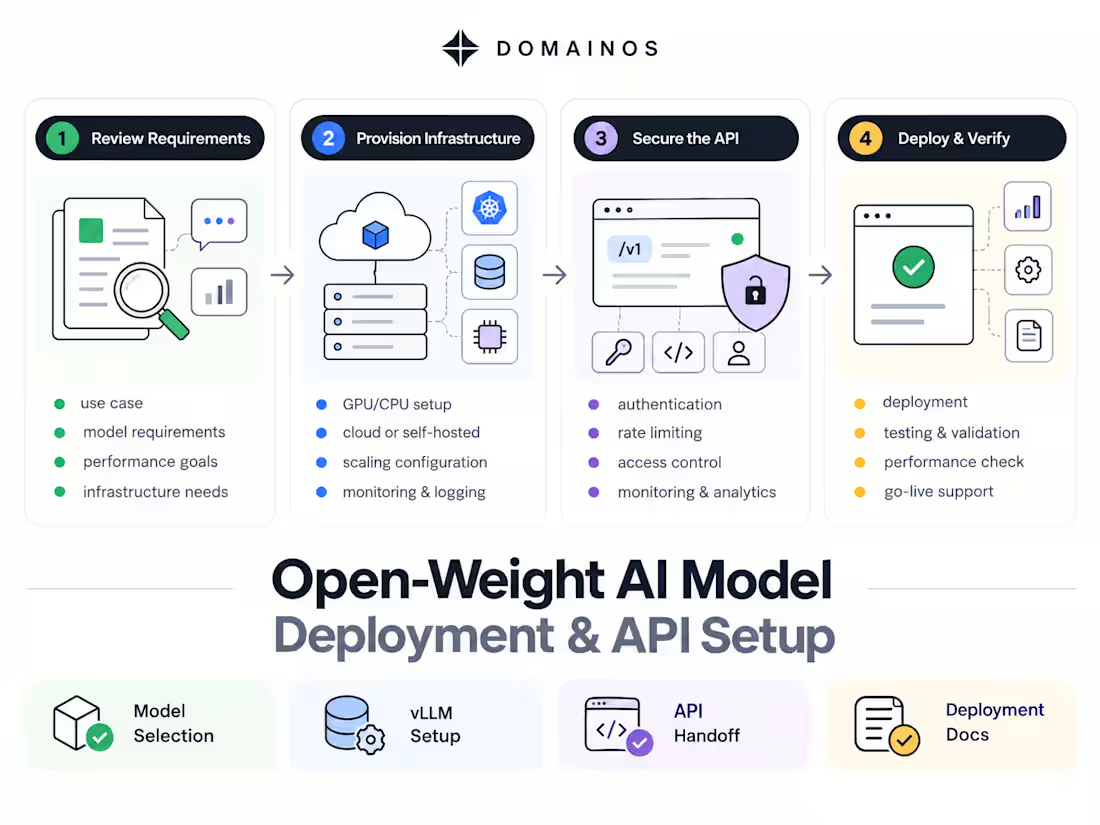
Model selection: Review your use case and choose one suitable, commercially deployable open-weight model.
GPU deployment: Set up one model on your cloud/GPU infrastructure.
Inference API: Configure an OpenAI-compatible API using a suitable inference engine, such as vLLM.
API security: Set up authentication, HTTPS access, and restricted public endpoints.
Testing: Verify model responses, API connectivity, authentication, and basic serving performance.
Documentation: Provide API usage examples, deployment configuration, and operating instructions.
Handover: Walk through the deployed service and explain how to access, operate, and maintain it.
How It Works
Discovery: Review your model requirements, intended workload, and infrastructure preferences.
Provisioning: You create or authorize access to your preferred GPU/cloud account.
Deployment: I configure and deploy your model and inference API.
Verification: We test the service against agreed acceptance criteria.
Handover: You receive your endpoint, API documentation, configuration, and operational instructions.
What You'll Receive
One deployed AI model
One authenticated HTTPS inference API
API integration example
Model and deployment configuration
Basic health and functionality test results
Deployment and handover documentation
Seven days of correction for defects within the agreed delivery scope
Requirements
You'll need an active cloud/GPU provider account, permission to deploy the selected model, and a funded infrastructure billing method.
GPU usage, hosting charges, fine-tuning, RAG integrations, application development, and ongoing maintenance are not included.
Ownership & Control
Your company retains control of its infrastructure account, data, proprietary configurations, and contractual rights to any customer-specific assets. Base model weights remain subject to their original licenses.
Delivery: Typically within 5 business days after requirements, access, and infrastructure readiness are confirmed, subject to model compatibility and agreed scope.
Price: $499 one-time.
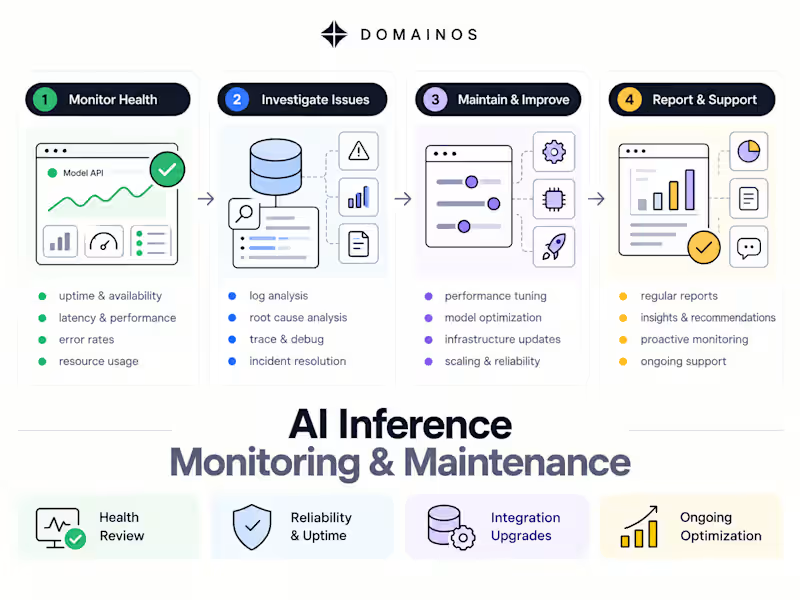
Ongoing monitoring, maintenance, and deployment support are available through a separate DomainOS monthly service.
DomainOS | Customer-Owned AI Infrastructure
FAQs
Starting at$499
Duration2 weeks
Tags
Docker
Hugging Face
Python
AI Engineer
API Integration
DevOps Engineer
LLM
Machine Learning
Cloud Computing
Service provided by
Ugo Chukwu proDubai - United Arab Emirates
- $10k+
- Earned
- 6
- Paid projects
- 4.95
- Rating
- 58
- Followers
Open-Weight AI Model Deployment & API SetupUgo Chukwu
Starting at$499
Duration2 weeks
Tags
Docker
Hugging Face
Python
AI Engineer
API Integration
DevOps Engineer
LLM
Machine Learning
Cloud Computing
Deploy Your Own AI Model. Own Your Infrastructure.
Get an open-weight AI model deployed, configured, and accessible through a secure API—without managing the deployment complexity yourself.
Through DomainOS Managed Inference, I help companies and developers deploy models such as Qwen, Llama, and other supported open-weight LLMs on their own GPU or cloud infrastructure.
Your infrastructure. Your model configuration. Your control.
What's Included
Model selection: Review your use case and choose one suitable, commercially deployable open-weight model.
GPU deployment: Set up one model on your cloud/GPU infrastructure.
Inference API: Configure an OpenAI-compatible API using a suitable inference engine, such as vLLM.
API security: Set up authentication, HTTPS access, and restricted public endpoints.
Testing: Verify model responses, API connectivity, authentication, and basic serving performance.
Documentation: Provide API usage examples, deployment configuration, and operating instructions.
Handover: Walk through the deployed service and explain how to access, operate, and maintain it.
How It Works
Discovery: Review your model requirements, intended workload, and infrastructure preferences.
Provisioning: You create or authorize access to your preferred GPU/cloud account.
Deployment: I configure and deploy your model and inference API.
Verification: We test the service against agreed acceptance criteria.
Handover: You receive your endpoint, API documentation, configuration, and operational instructions.
What You'll Receive
One deployed AI model
One authenticated HTTPS inference API
API integration example
Model and deployment configuration
Basic health and functionality test results
Deployment and handover documentation
Seven days of correction for defects within the agreed delivery scope
Requirements
You'll need an active cloud/GPU provider account, permission to deploy the selected model, and a funded infrastructure billing method.
GPU usage, hosting charges, fine-tuning, RAG integrations, application development, and ongoing maintenance are not included.
Ownership & Control
Your company retains control of its infrastructure account, data, proprietary configurations, and contractual rights to any customer-specific assets. Base model weights remain subject to their original licenses.
Delivery: Typically within 5 business days after requirements, access, and infrastructure readiness are confirmed, subject to model compatibility and agreed scope.
Price: $499 one-time.
Ongoing monitoring, maintenance, and deployment support are available through a separate DomainOS monthly service.
DomainOS | Customer-Owned AI Infrastructure
FAQs
$499