LLM Cost & Architecture OptimizationChristian Spilhere
Understand your AI spend. Reduce waste. Protect the quality users depend on.
When LLM usage grows, small architectural decisions become expensive. A single model handling every task, oversized requests, repeated calls, and poorly controlled retries can make costs difficult to predict.
I help teams understand what drives their AI spend and implement targeted improvements, using representative evaluations to assess the effect on quality and reliability.
WHAT I CAN HELP WITH
• Analyze model usage, request patterns, and cost drivers.
• Match model capabilities to the needs of each task.
• Design multi-provider routing and fallback behavior.
• Review prompt size, token budgets, repeated calls, and retry logic.
• Add telemetry to make cost and failure patterns visible.
• Evaluate optimization options against real application examples.
WHAT YOU GET
• A baseline of current usage, costs, and available quality signals.
• A prioritized optimization plan with explicit tradeoffs.
• Implemented improvements for the agreed scope.
• A before-and-after comparison using representative workloads.
• Documentation of routing decisions, fallback behavior, and remaining opportunities.
HOW WE WORK
We begin with your application’s goals, current architecture, and available usage data. Together, we define the quality criteria that matter. I identify the strongest opportunities, implement the agreed changes, and compare the results against the baseline.
Savings depend on your starting architecture and workload. The engagement focuses on measurable improvements, with quality and reliability evaluated alongside cost.
WHY ME
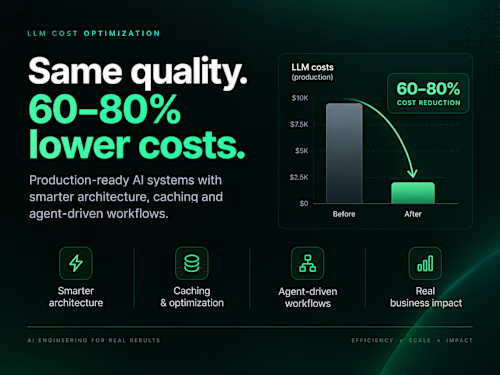
For Ana M, I designed and implemented multi-provider LLM routing using OpenAI and Gemini, with semantic fallback and cost telemetry. That work reduced production LLM costs by 60–80% while maintaining output quality and reliability.
Share your current providers, approximate monthly LLM spend, and main AI use cases. We’ll identify a focused starting point.
FAQs
Example work
Contact for pricing
Duration2 weeks
Tags
Google Cloud Platform
OpenAI
AI Engineer
Service provided by
Christian Spilhere Florianópolis, Brazil
LLM Cost & Architecture OptimizationChristian Spilhere
Understand your AI spend. Reduce waste. Protect the quality users depend on.
When LLM usage grows, small architectural decisions become expensive. A single model handling every task, oversized requests, repeated calls, and poorly controlled retries can make costs difficult to predict.
I help teams understand what drives their AI spend and implement targeted improvements, using representative evaluations to assess the effect on quality and reliability.
WHAT I CAN HELP WITH
• Analyze model usage, request patterns, and cost drivers.
• Match model capabilities to the needs of each task.
• Design multi-provider routing and fallback behavior.
• Review prompt size, token budgets, repeated calls, and retry logic.
• Add telemetry to make cost and failure patterns visible.
• Evaluate optimization options against real application examples.
WHAT YOU GET
• A baseline of current usage, costs, and available quality signals.
• A prioritized optimization plan with explicit tradeoffs.
• Implemented improvements for the agreed scope.
• A before-and-after comparison using representative workloads.
• Documentation of routing decisions, fallback behavior, and remaining opportunities.
HOW WE WORK
We begin with your application’s goals, current architecture, and available usage data. Together, we define the quality criteria that matter. I identify the strongest opportunities, implement the agreed changes, and compare the results against the baseline.
Savings depend on your starting architecture and workload. The engagement focuses on measurable improvements, with quality and reliability evaluated alongside cost.
WHY ME
For Ana M, I designed and implemented multi-provider LLM routing using OpenAI and Gemini, with semantic fallback and cost telemetry. That work reduced production LLM costs by 60–80% while maintaining output quality and reliability.
Share your current providers, approximate monthly LLM spend, and main AI use cases. We’ll identify a focused starting point.
FAQs
Example work
Contact for pricing