Machine Learning Engineering, Model Evaluation & LLM BenchmarkinOmar Hashmi
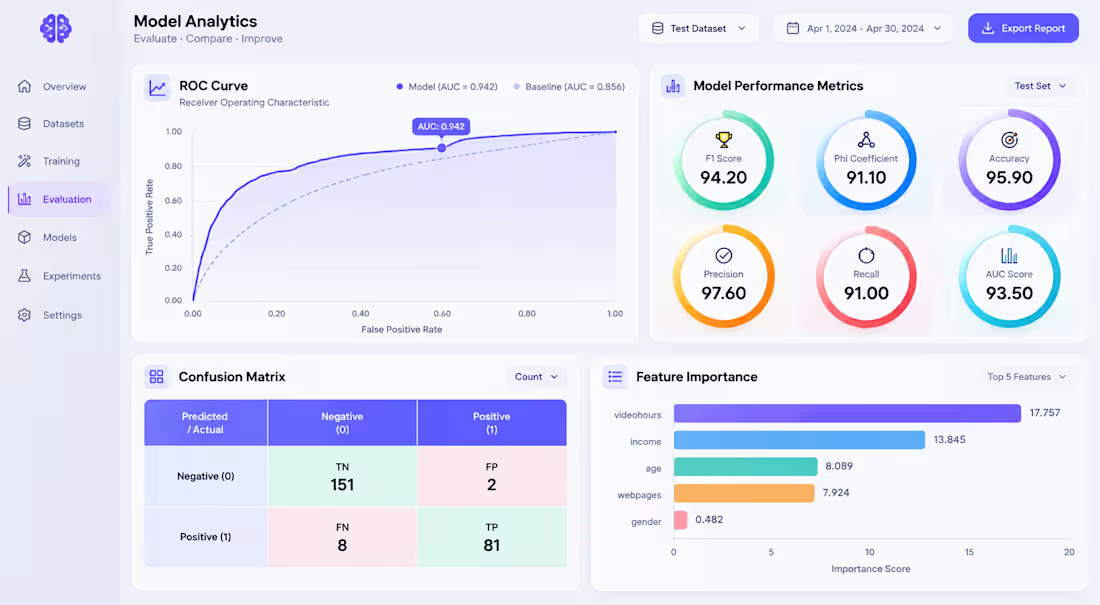
I help teams build, evaluate, and improve machine learning systems through practical experimentation, model development, and structured evaluation.
My experience spans software engineering and AI product development, including tabular machine learning, NLP, and LLM-focused workflows.
Services include:
Machine learning model development
Classification, regression, and prediction pipelines
Tabular ML with suitable algorithms such as LightGBM, XGBoost, and CatBoost
NLP and transformer-based model integration
LLM evaluation and benchmark design
Model comparison and error analysis
Data preprocessing and feature engineering
Evaluation metrics, experiment tracking, and reproducible testing
Python-based ML pipelines and integration into applications
I aim to make experiments measurable and results understandable, with attention to data quality, evaluation methodology, and the limitations of each approach.
For LLM evaluation, the methodology can include task-specific test sets, scoring criteria, model comparisons, and analysis of failure cases.
Send your dataset or evaluation objective, along with your expected outputs, and we can establish the scope and methodology.
FAQs
Starting at$150
Duration1 week
Tags
LLM Evaluation
Python
PyTorch

scikit-learn
Data Scientist
Machine Learning
NLP
AI Research
Model Benchmarking
Service provided by
Omar Hashmi Mumbai, India
- 1
- Followers
Machine Learning Engineering, Model Evaluation & LLM BenchmarkinOmar Hashmi
Starting at$150
Duration1 week
Tags
LLM Evaluation
Python
PyTorch
scikit-learn
Data Scientist
Machine Learning
NLP
AI Research
Model Benchmarking
I help teams build, evaluate, and improve machine learning systems through practical experimentation, model development, and structured evaluation.
My experience spans software engineering and AI product development, including tabular machine learning, NLP, and LLM-focused workflows.
Services include:
Machine learning model development
Classification, regression, and prediction pipelines
Tabular ML with suitable algorithms such as LightGBM, XGBoost, and CatBoost
NLP and transformer-based model integration
LLM evaluation and benchmark design
Model comparison and error analysis
Data preprocessing and feature engineering
Evaluation metrics, experiment tracking, and reproducible testing
Python-based ML pipelines and integration into applications
I aim to make experiments measurable and results understandable, with attention to data quality, evaluation methodology, and the limitations of each approach.
For LLM evaluation, the methodology can include task-specific test sets, scoring criteria, model comparisons, and analysis of failure cases.
Send your dataset or evaluation objective, along with your expected outputs, and we can establish the scope and methodology.
FAQs
$150