
Custom RAG & Intelligent Knowledge Base AssistantKaran Singh
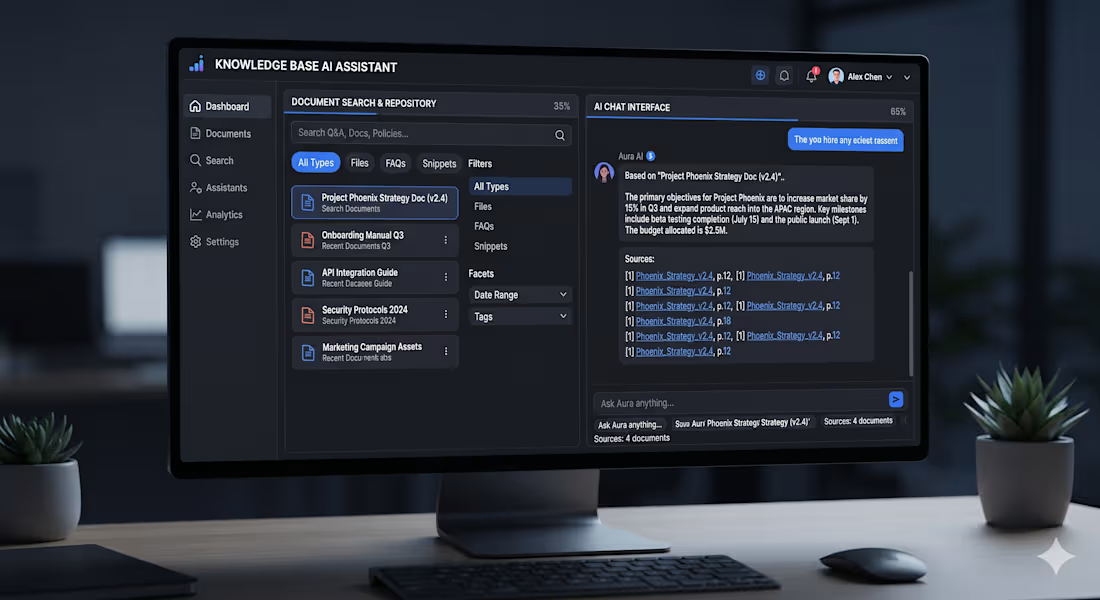
Build an enterprise-grade Retrieval-Augmented Generation (RAG) system that allows your team or users to query internal documents, PDFs, manuals, or databases with high precision and zero hallucinations.
MVP: A working prototype indexing up to 50 sample documents with semantic search, metadata filtering, and a clean chat interface.
Pricing : $3,999
Timeline: 7–14 days
What You Get:
Custom document ingestion & chunking pipeline (supports PDF, TXT, DOCX, Markdown).
Vector database integration (e.g., Qdrant or pgvector or supabase).
FastAPI backend endpoint for querying.
Modern frontend chat interface dashboard with Authentication.
How We Work Together (Our Workflow)
Requirements -> Project request sent to me
Planning -> Research & implementation plan creation
Verification -> Plan review & client sign-off
Execution -> Development with 24-hr regular updates & upfront optimizations
Testing -> Live link deployment for client testing & feedback
Handover -> Final 50% payment & project delivery
Important Notes:
Payment: 50% upfront before the project commences within 24-48hrs of the payment successful.
Infrastructure Costs: All third-party costs—including LLM API tokens, vector database hosting, cloud deployment servers, and GPU compute—are to be paid directly by the client.
The given pricing and timings are based on standard requirements, both can vary depending on your specific custom needs.
FAQs
Starting at$3,999
Duration2 weeks
Tags
Document Processing
FastAPI
LLM Integration
Python
Vector Database
API Development
Artificial Intelligence
Natural Language Processing (NLP)
Retrieval-Augmented Generation (RAG)
Service provided by
Karan Singh Kangra, India
- 13
- Followers
Custom RAG & Intelligent Knowledge Base AssistantKaran Singh
Starting at$3,999
Duration2 weeks
Tags
Document Processing
FastAPI
LLM Integration
Python
Vector Database
API Development
Artificial Intelligence
Natural Language Processing (NLP)
Retrieval-Augmented Generation (RAG)
Build an enterprise-grade Retrieval-Augmented Generation (RAG) system that allows your team or users to query internal documents, PDFs, manuals, or databases with high precision and zero hallucinations.
MVP: A working prototype indexing up to 50 sample documents with semantic search, metadata filtering, and a clean chat interface.
Pricing : $3,999
Timeline: 7–14 days
What You Get:
Custom document ingestion & chunking pipeline (supports PDF, TXT, DOCX, Markdown).
Vector database integration (e.g., Qdrant or pgvector or supabase).
FastAPI backend endpoint for querying.
Modern frontend chat interface dashboard with Authentication.
How We Work Together (Our Workflow)
Requirements -> Project request sent to me
Planning -> Research & implementation plan creation
Verification -> Plan review & client sign-off
Execution -> Development with 24-hr regular updates & upfront optimizations
Testing -> Live link deployment for client testing & feedback
Handover -> Final 50% payment & project delivery
Important Notes:
Payment: 50% upfront before the project commences within 24-48hrs of the payment successful.
Infrastructure Costs: All third-party costs—including LLM API tokens, vector database hosting, cloud deployment servers, and GPU compute—are to be paid directly by the client.
The given pricing and timings are based on standard requirements, both can vary depending on your specific custom needs.
FAQs
$3,999