AI Prototype to ProductionJhoan Sebastian Duque Zapata
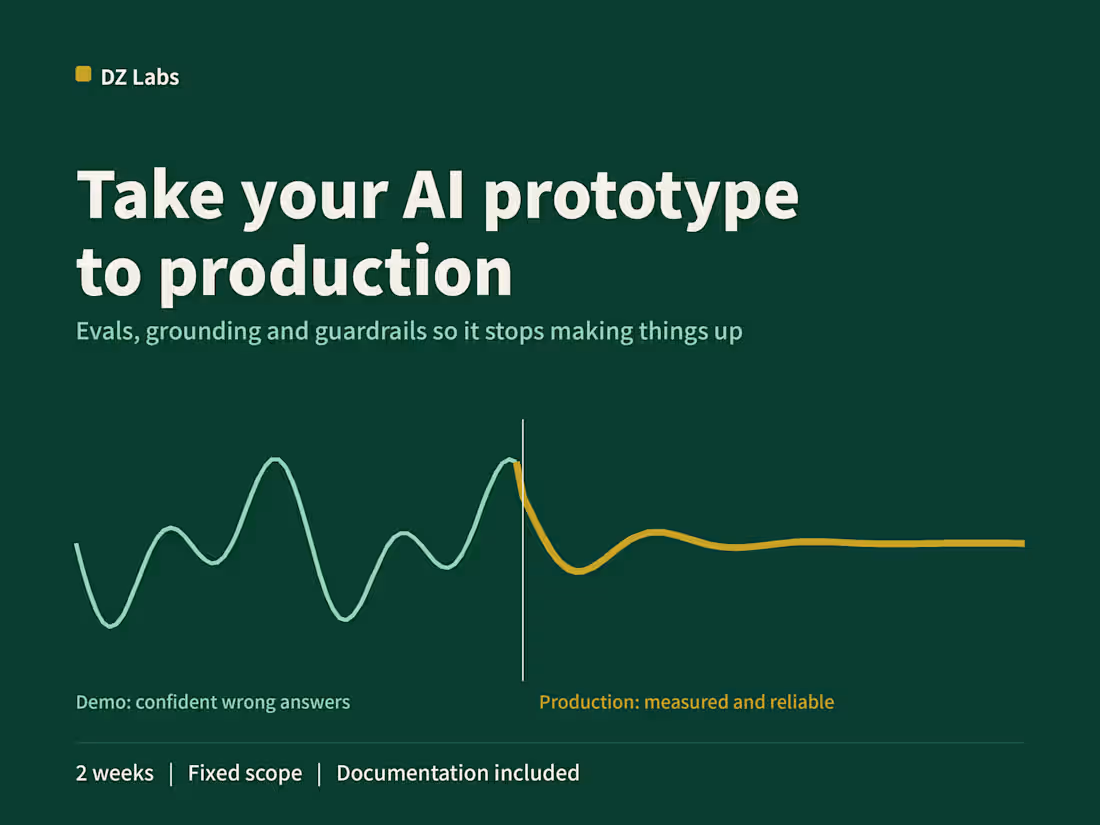
Your AI demo looks great, until it meets real data. It gives confident wrong answers, costs more than expected, and nobody can tell whether a change made it better or worse.
I take AI prototypes and make them reliable enough to put in front of customers.
What I fix
Wrong answers: better retrieval, chunking and grounding, so answers come from your data and the system says “I don’t know” instead of inventing
No way to measure quality: an evaluation set built from your real use cases, including tricky and unanswerable questions, run before every change
Unpredictable outputs: structured outputs validated against a schema, with retries and fallbacks
Rising costs: token and cost tracking per request, plus the right model for each task
Knowledge gaps: clear documentation of the architecture so your team can maintain it
How it works
Kickoff call to define success criteria and scope
I measure the current quality with an evaluation set built from your examples
I fix the issues and show you before and after scores
Final review and handover with documentation
Good fit if you built something with Lovable, Cursor, a no-code tool or a quick LangChain prototype, and it isn’t ready for real users yet.
FAQs

Jhoan Sebastian's other services
Starting at$3,000
Duration2 weeks
Tags
Claude
LangChain
OpenAI
Python
RAG
Generative AI
LLM
Prompt Engineer
AI Evaluation
Service provided by
Jhoan Sebastian Duque Zapata Bogota, Colombia
- 7
- Followers
AI Prototype to ProductionJhoan Sebastian Duque Zapata
Starting at$3,000
Duration2 weeks
Tags
Claude
LangChain
OpenAI
Python
RAG
Generative AI
LLM
Prompt Engineer
AI Evaluation
Your AI demo looks great, until it meets real data. It gives confident wrong answers, costs more than expected, and nobody can tell whether a change made it better or worse.
I take AI prototypes and make them reliable enough to put in front of customers.
What I fix
Wrong answers: better retrieval, chunking and grounding, so answers come from your data and the system says “I don’t know” instead of inventing
No way to measure quality: an evaluation set built from your real use cases, including tricky and unanswerable questions, run before every change
Unpredictable outputs: structured outputs validated against a schema, with retries and fallbacks
Rising costs: token and cost tracking per request, plus the right model for each task
Knowledge gaps: clear documentation of the architecture so your team can maintain it
How it works
Kickoff call to define success criteria and scope
I measure the current quality with an evaluation set built from your examples
I fix the issues and show you before and after scores
Final review and handover with documentation
Good fit if you built something with Lovable, Cursor, a no-code tool or a quick LangChain prototype, and it isn’t ready for real users yet.
FAQs
Jhoan Sebastian's other services
$3,000