RAG AI Chatbot & Knowledge AssistantAbdul Rehman
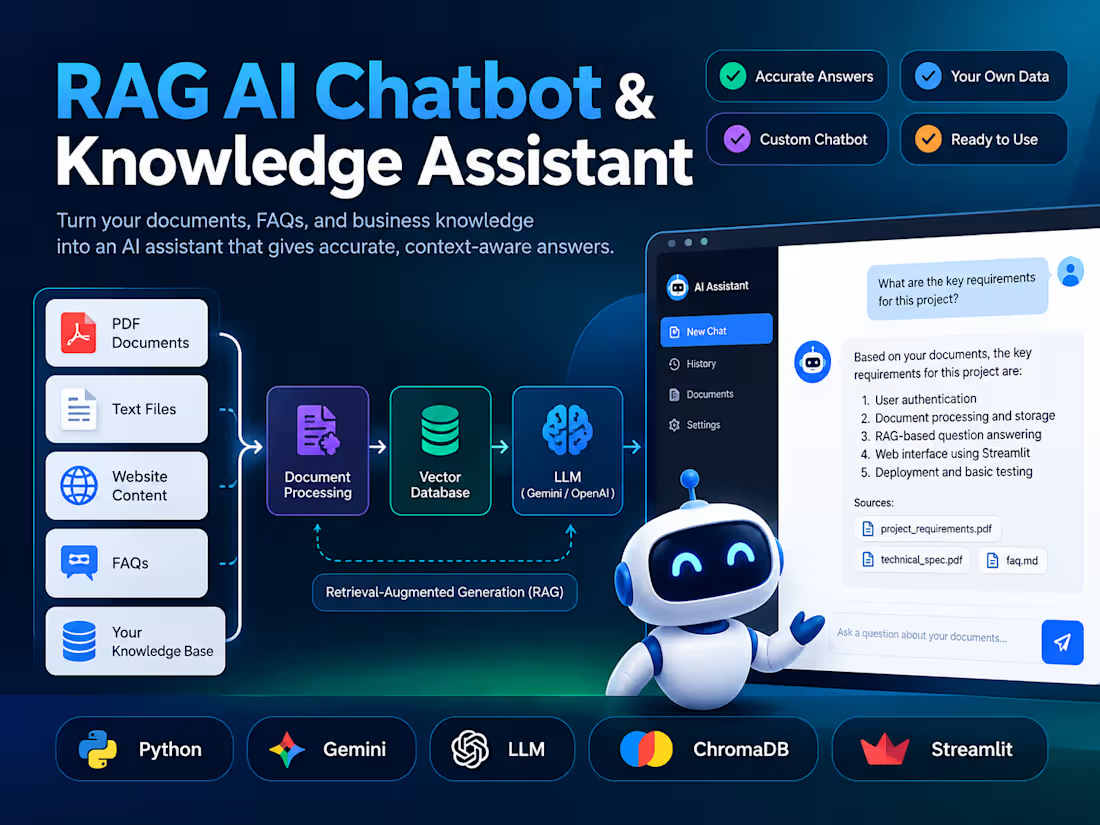
I build RAG-powered AI chatbots and knowledge assistants that let users ask questions and receive context-aware answers from your own documents, FAQs, website content, or knowledge base.
What I can build
Document and knowledge-base Q&A assistants
PDF, text, FAQ, and website-content retrieval
Retrieval-Augmented Generation (RAG) pipelines
LLM-powered question answering
Vector search and semantic retrieval
AI chat interfaces with Streamlit
Context-aware responses grounded in your provided data
Basic conversation and retrieval testing
Typical workflow
Your content → preprocessing → chunking → embeddings/retrieval → relevant context → LLM → grounded response → user-facing chatbot
What you receive
RAG pipeline connected to your knowledge source
Document ingestion and preprocessing
Retrieval/search component
LLM response generation
Interactive chatbot interface where required
Source code and project structure
Basic testing and documentation
Technologies
Python, Gemini/LLMs, ChromaDB, vector search, NLP, Streamlit, and related AI tools.
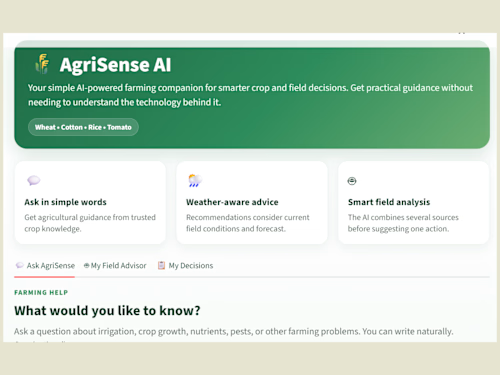
I have hands-on experience building AgriSense AI, a RAG-based agronomy advisor using Gemini, ChromaDB, TF-IDF retrieval, and Streamlit. This project involved combining retrieval with generative AI to produce responses based on a defined knowledge source.
Suitable for
Internal knowledge assistants, document Q&A, FAQ bots, research assistants, support knowledge bases, educational assistants, and other applications where an LLM needs to work with your own information.
I focus on grounded responses, clear retrieval workflows, maintainable code, and practical implementation rather than simply connecting an LLM to a chat interface.
FAQs
Example work
Starting at$150
Duration1 week
Tags
Python
RAG
Streamlit
Vector Databases
AI Chatbot Developer
AI Engineer
Generative AI
LLM
Natural Language Processing
Service provided by
Abdul Rehman Sialkot, Pakistan
RAG AI Chatbot & Knowledge AssistantAbdul Rehman
Starting at$150
Duration1 week
Tags
Python
RAG
Streamlit
Vector Databases
AI Chatbot Developer
AI Engineer
Generative AI
LLM
Natural Language Processing
I build RAG-powered AI chatbots and knowledge assistants that let users ask questions and receive context-aware answers from your own documents, FAQs, website content, or knowledge base.
What I can build
Document and knowledge-base Q&A assistants
PDF, text, FAQ, and website-content retrieval
Retrieval-Augmented Generation (RAG) pipelines
LLM-powered question answering
Vector search and semantic retrieval
AI chat interfaces with Streamlit
Context-aware responses grounded in your provided data
Basic conversation and retrieval testing
Typical workflow
Your content → preprocessing → chunking → embeddings/retrieval → relevant context → LLM → grounded response → user-facing chatbot
What you receive
RAG pipeline connected to your knowledge source
Document ingestion and preprocessing
Retrieval/search component
LLM response generation
Interactive chatbot interface where required
Source code and project structure
Basic testing and documentation
Technologies
Python, Gemini/LLMs, ChromaDB, vector search, NLP, Streamlit, and related AI tools.
I have hands-on experience building AgriSense AI, a RAG-based agronomy advisor using Gemini, ChromaDB, TF-IDF retrieval, and Streamlit. This project involved combining retrieval with generative AI to produce responses based on a defined knowledge source.
Suitable for
Internal knowledge assistants, document Q&A, FAQ bots, research assistants, support knowledge bases, educational assistants, and other applications where an LLM needs to work with your own information.
I focus on grounded responses, clear retrieval workflows, maintainable code, and practical implementation rather than simply connecting an LLM to a chat interface.
FAQs
Example work
$150