AI Evaluation Specialist, Data Annotation & QA SpecialistLeia Gregory
AI Experience
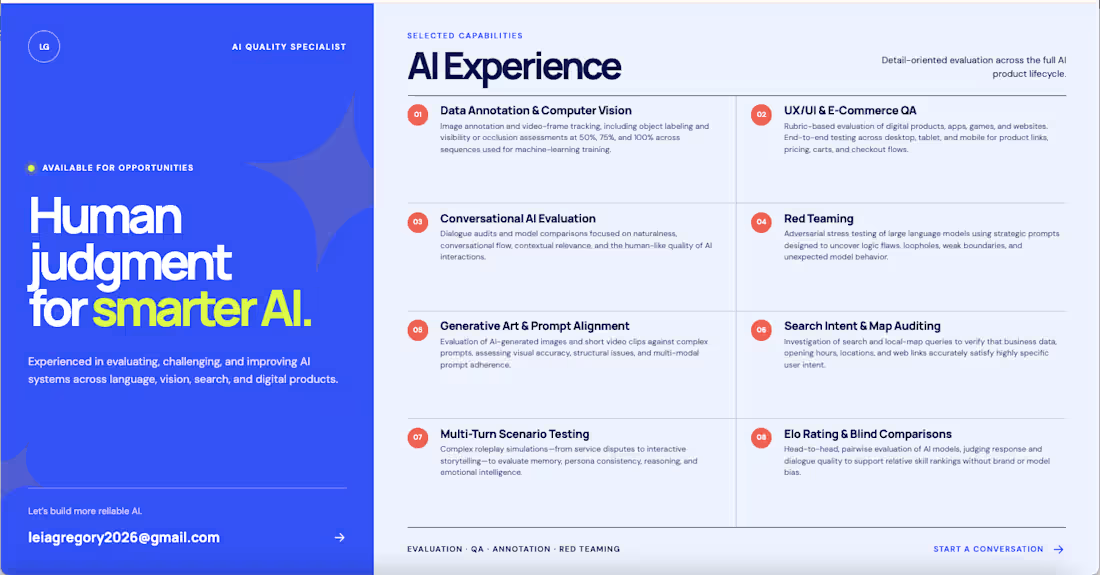
Data Annotation & Computer Vision: Annotated images and performed video frame tracking, labeling visible objects and assessing object visibility/occlusion percentages (50%, 75%, 100%) across video sequences for machine learning training.
UX/UI & E-Commerce Quality Assurance (QA): Evaluated digital products, apps, games, and websites against specific rubrics; conducted rigorous end-to-end testing on e-commerce platforms across desktop, tablet, and mobile devices to verify product links, correct pricing, cart functionality, and checkout flows.
Conversational AI Evaluation: Audited and compared dialogue interactions to evaluate naturalness, conversational flow, and human-likeness between AI models.
Red Teaming: Acted as an adversarial user to stress-test large language models, attempting to find logic flaws, loopholes, or boundaries by crafting clever prompts to break or trick the system.
Generative Art & Multi-Modal Prompt Alignment: Evaluated AI-generated images and short video clips against complex text prompts, assessing visual accuracy, structural flaws, and prompt adherence.
Search Intent and Map/Local Query Auditing: Investigated search engine and map queries to determine whether real-world business data, hours, locations, and web links accurately satisfied hyper-specific user intent.
Multi-Turn Roleplay and Interactive Scenario Testing: Simulated complex conversational scenarios (such as customer service disputes or interactive storytelling) to evaluate an AI's memory, persona maintenance, and emotional intelligence.
Elo Rating & Blind Comparisons: Conducted head-to-head blind evaluations of AI models using pairwise comparison systems, judging which responses or dialogues performed better to update relative skill rankings.
Contact for pricing
Duration1 week
Tags
AI Content Editor
Media Trainer
AI automations
AI prompts
Service provided by
Leia Gregory St. Petersburg, USA
- 1
- Followers
AI Evaluation Specialist, Data Annotation & QA SpecialistLeia Gregory
Contact for pricing
Duration1 week
Tags
AI Content Editor
Media Trainer
AI automations
AI prompts
AI Experience
Data Annotation & Computer Vision: Annotated images and performed video frame tracking, labeling visible objects and assessing object visibility/occlusion percentages (50%, 75%, 100%) across video sequences for machine learning training.
UX/UI & E-Commerce Quality Assurance (QA): Evaluated digital products, apps, games, and websites against specific rubrics; conducted rigorous end-to-end testing on e-commerce platforms across desktop, tablet, and mobile devices to verify product links, correct pricing, cart functionality, and checkout flows.
Conversational AI Evaluation: Audited and compared dialogue interactions to evaluate naturalness, conversational flow, and human-likeness between AI models.
Red Teaming: Acted as an adversarial user to stress-test large language models, attempting to find logic flaws, loopholes, or boundaries by crafting clever prompts to break or trick the system.
Generative Art & Multi-Modal Prompt Alignment: Evaluated AI-generated images and short video clips against complex text prompts, assessing visual accuracy, structural flaws, and prompt adherence.
Search Intent and Map/Local Query Auditing: Investigated search engine and map queries to determine whether real-world business data, hours, locations, and web links accurately satisfied hyper-specific user intent.
Multi-Turn Roleplay and Interactive Scenario Testing: Simulated complex conversational scenarios (such as customer service disputes or interactive storytelling) to evaluate an AI's memory, persona maintenance, and emotional intelligence.
Elo Rating & Blind Comparisons: Conducted head-to-head blind evaluations of AI models using pairwise comparison systems, judging which responses or dialogues performed better to update relative skill rankings.
Contact for pricing