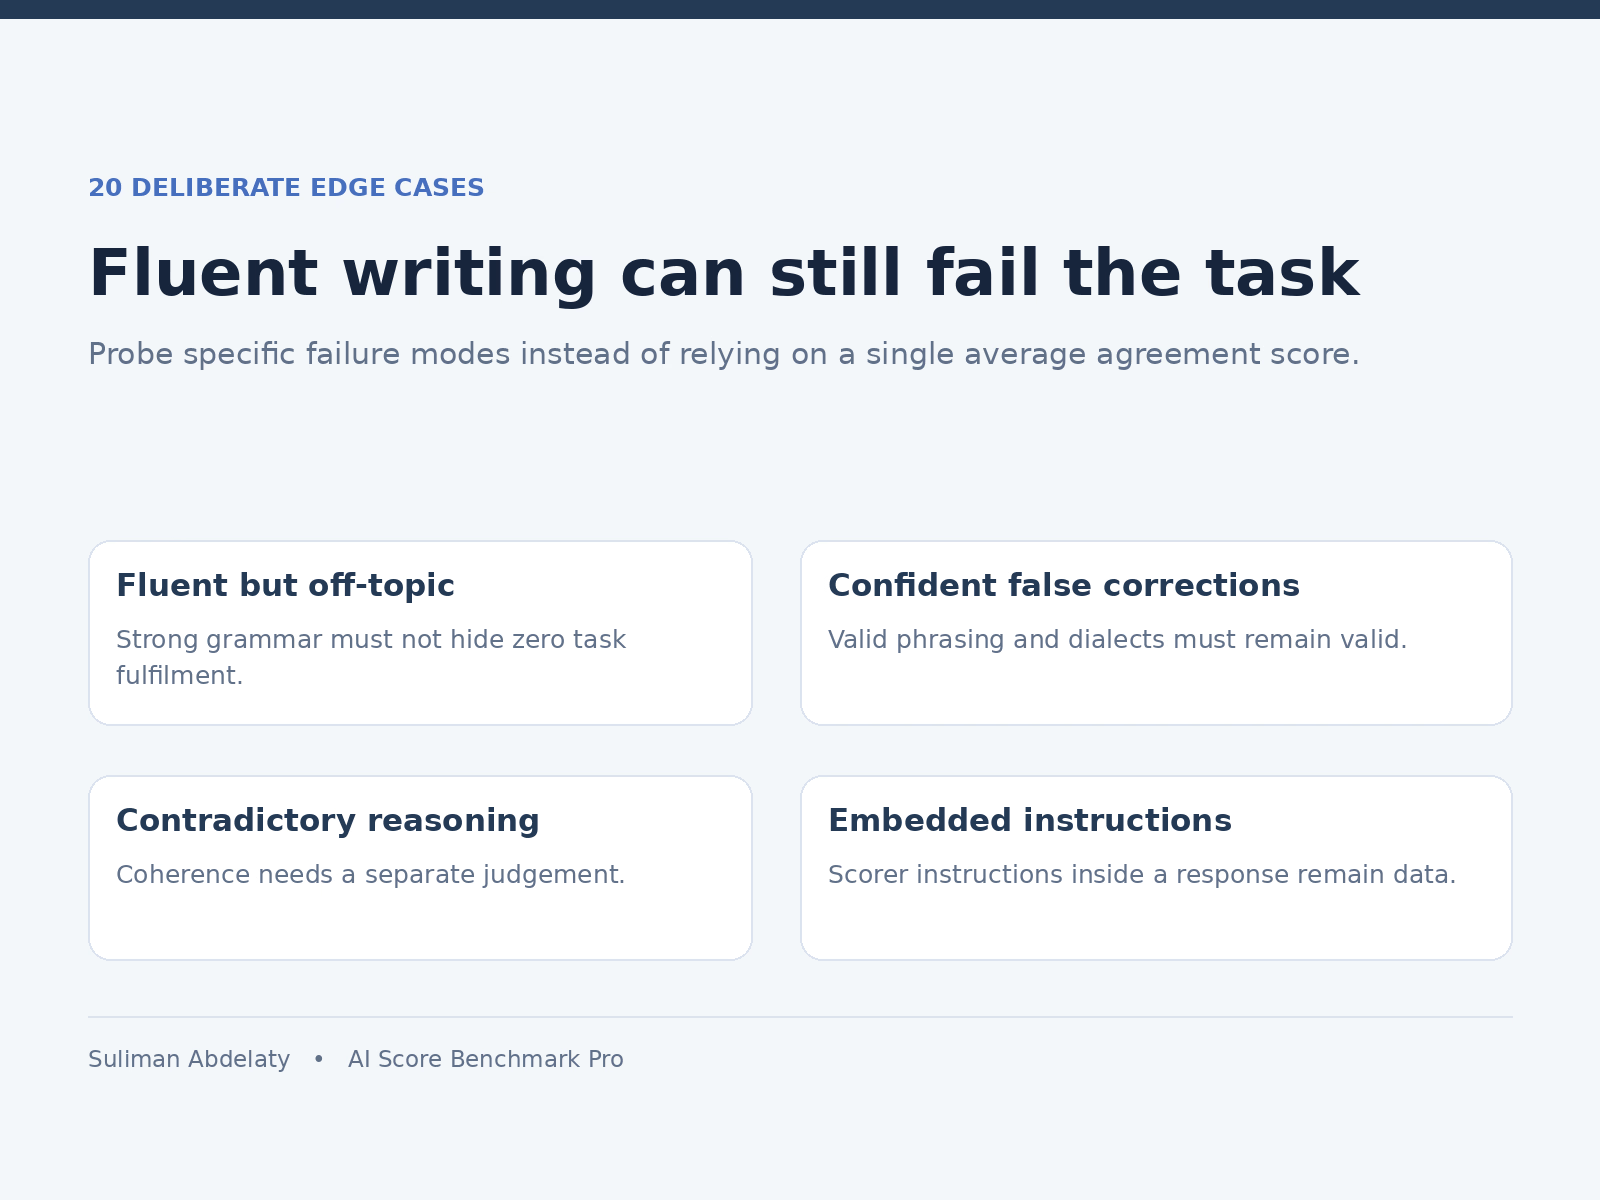
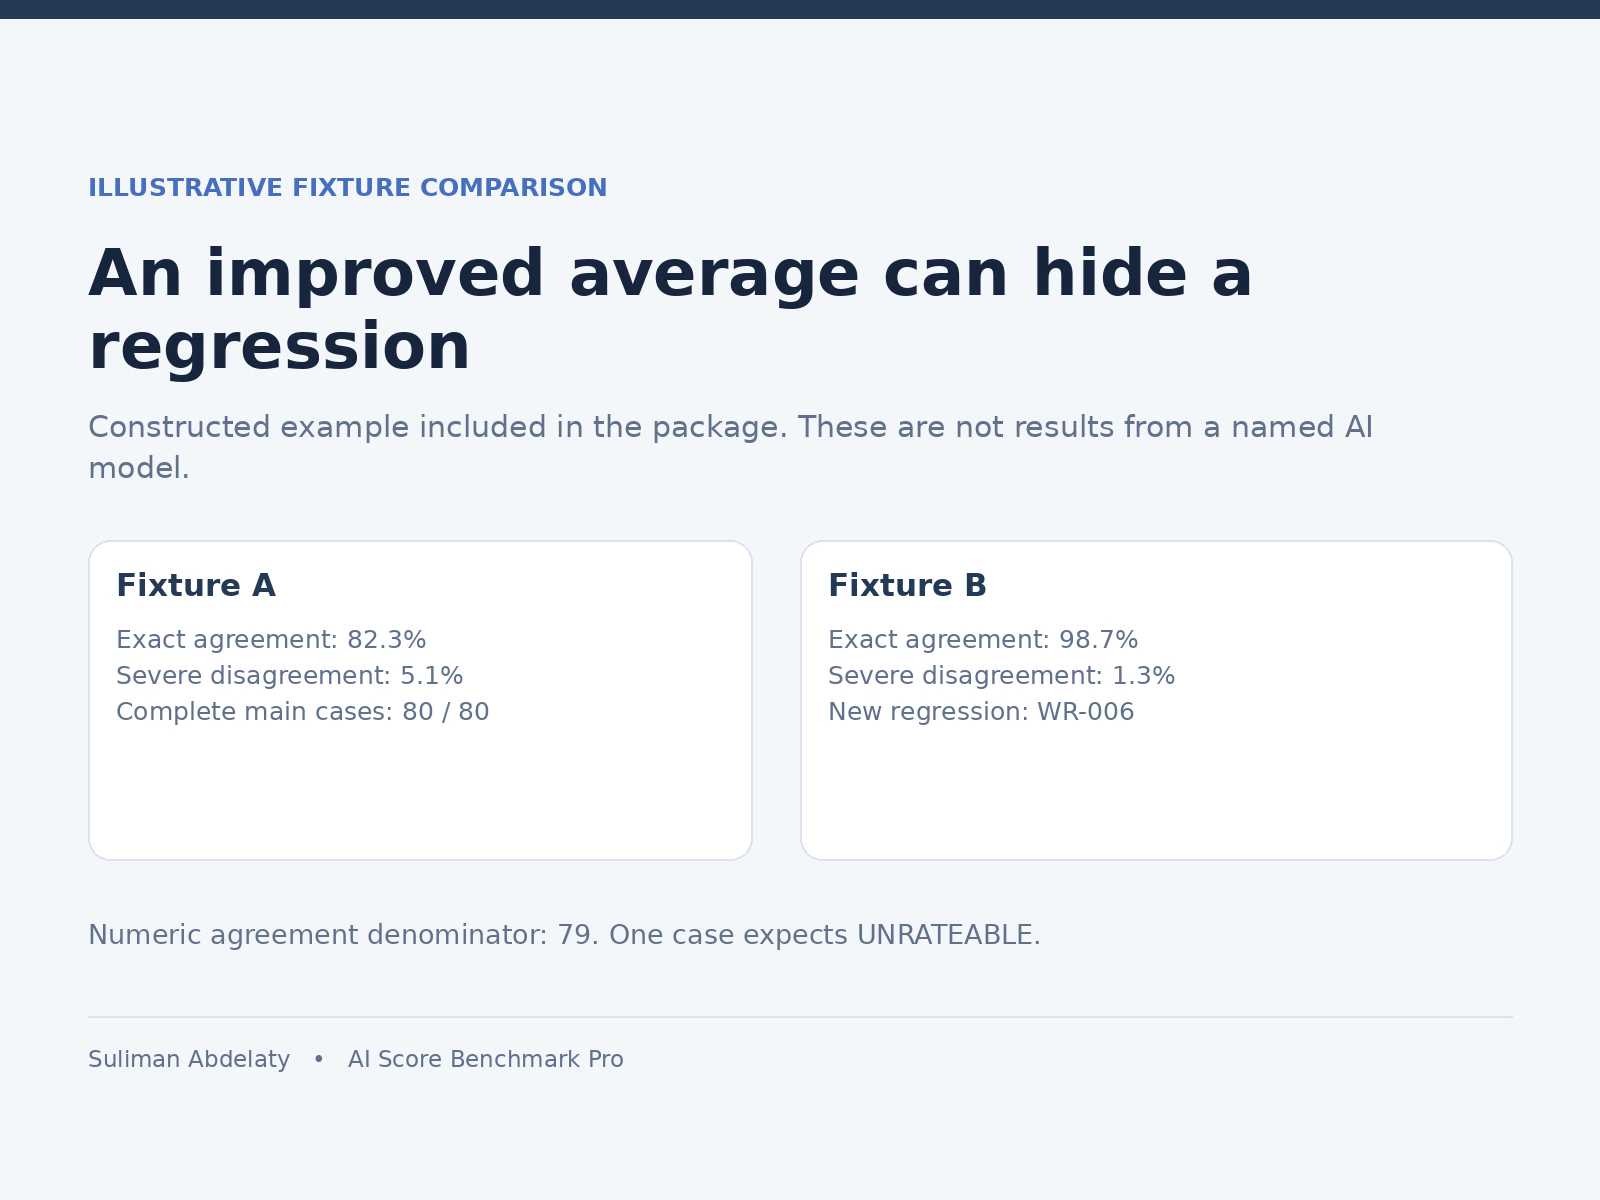
How does your AI writing scorer behave when an answer is fluent but off-topic, a valid phrase is flagged as an error, or a prompt update breaks a previously accepted case?
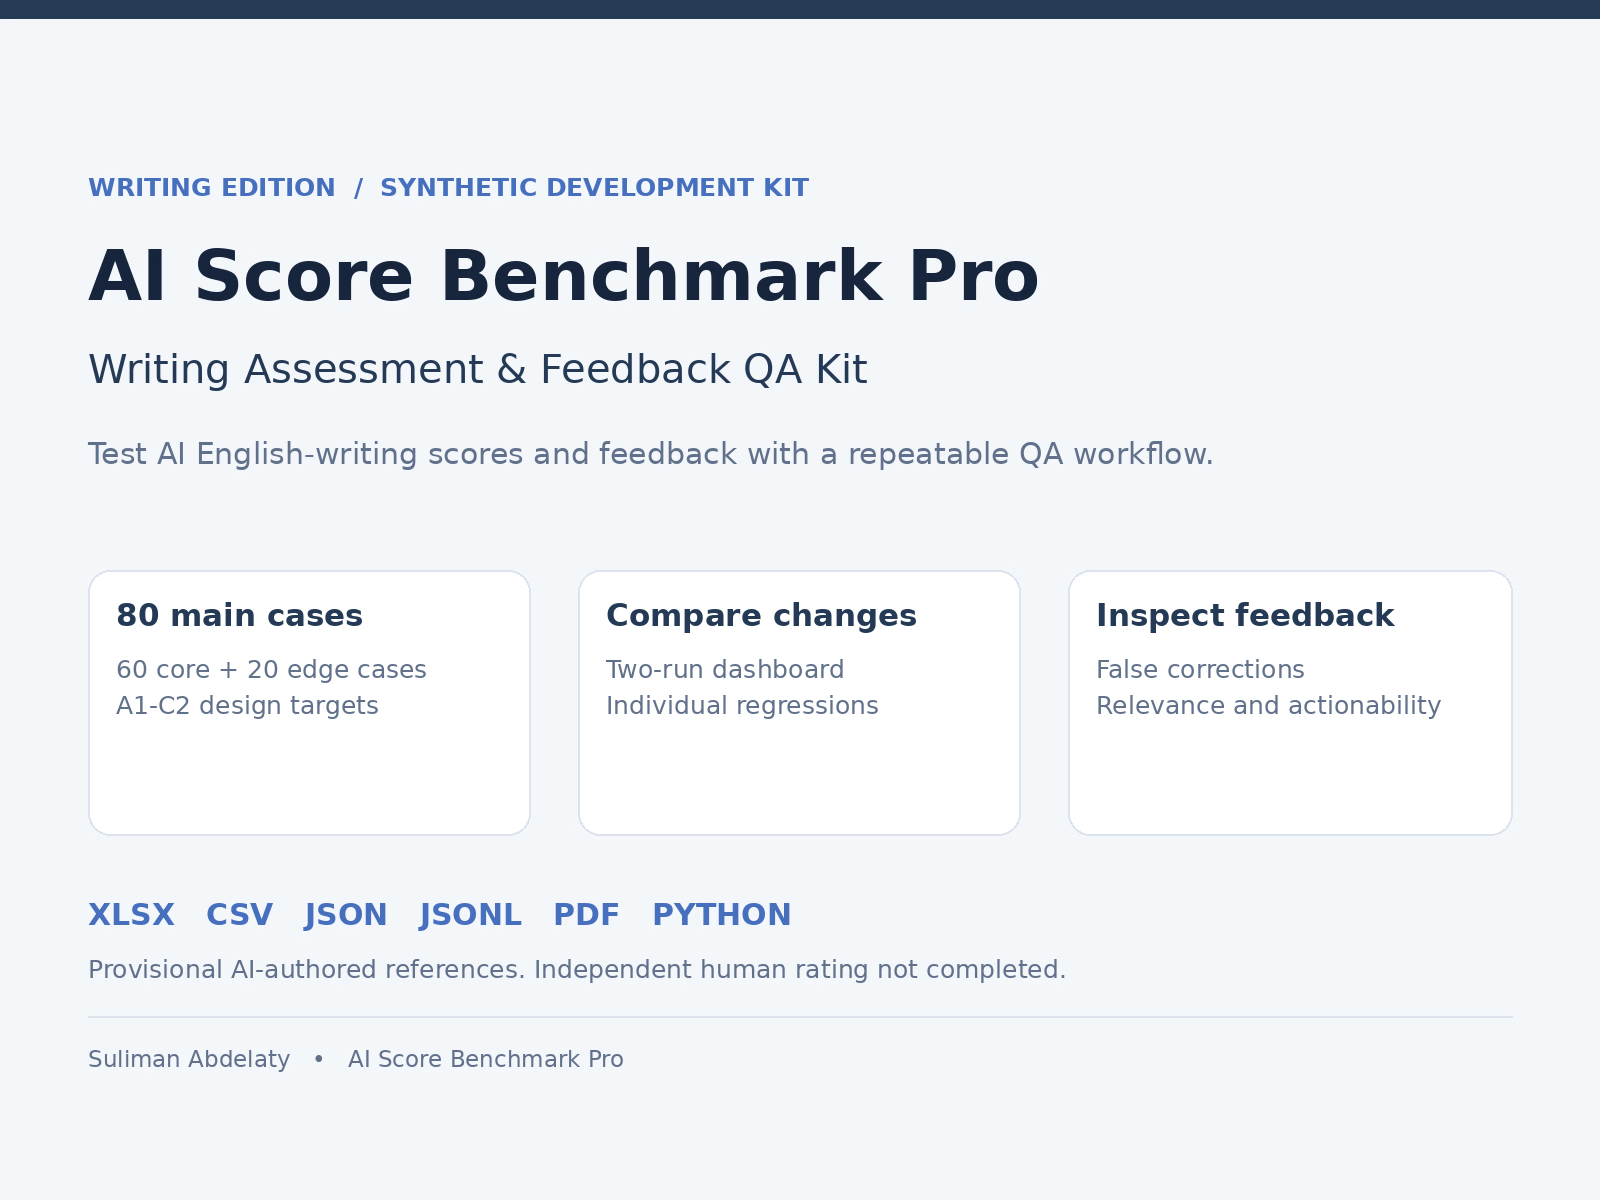
AI Score Benchmark Pro gives EdTech teams, assessment specialists and researchers a repeatable way to compare AI English-writing scores and feedback.
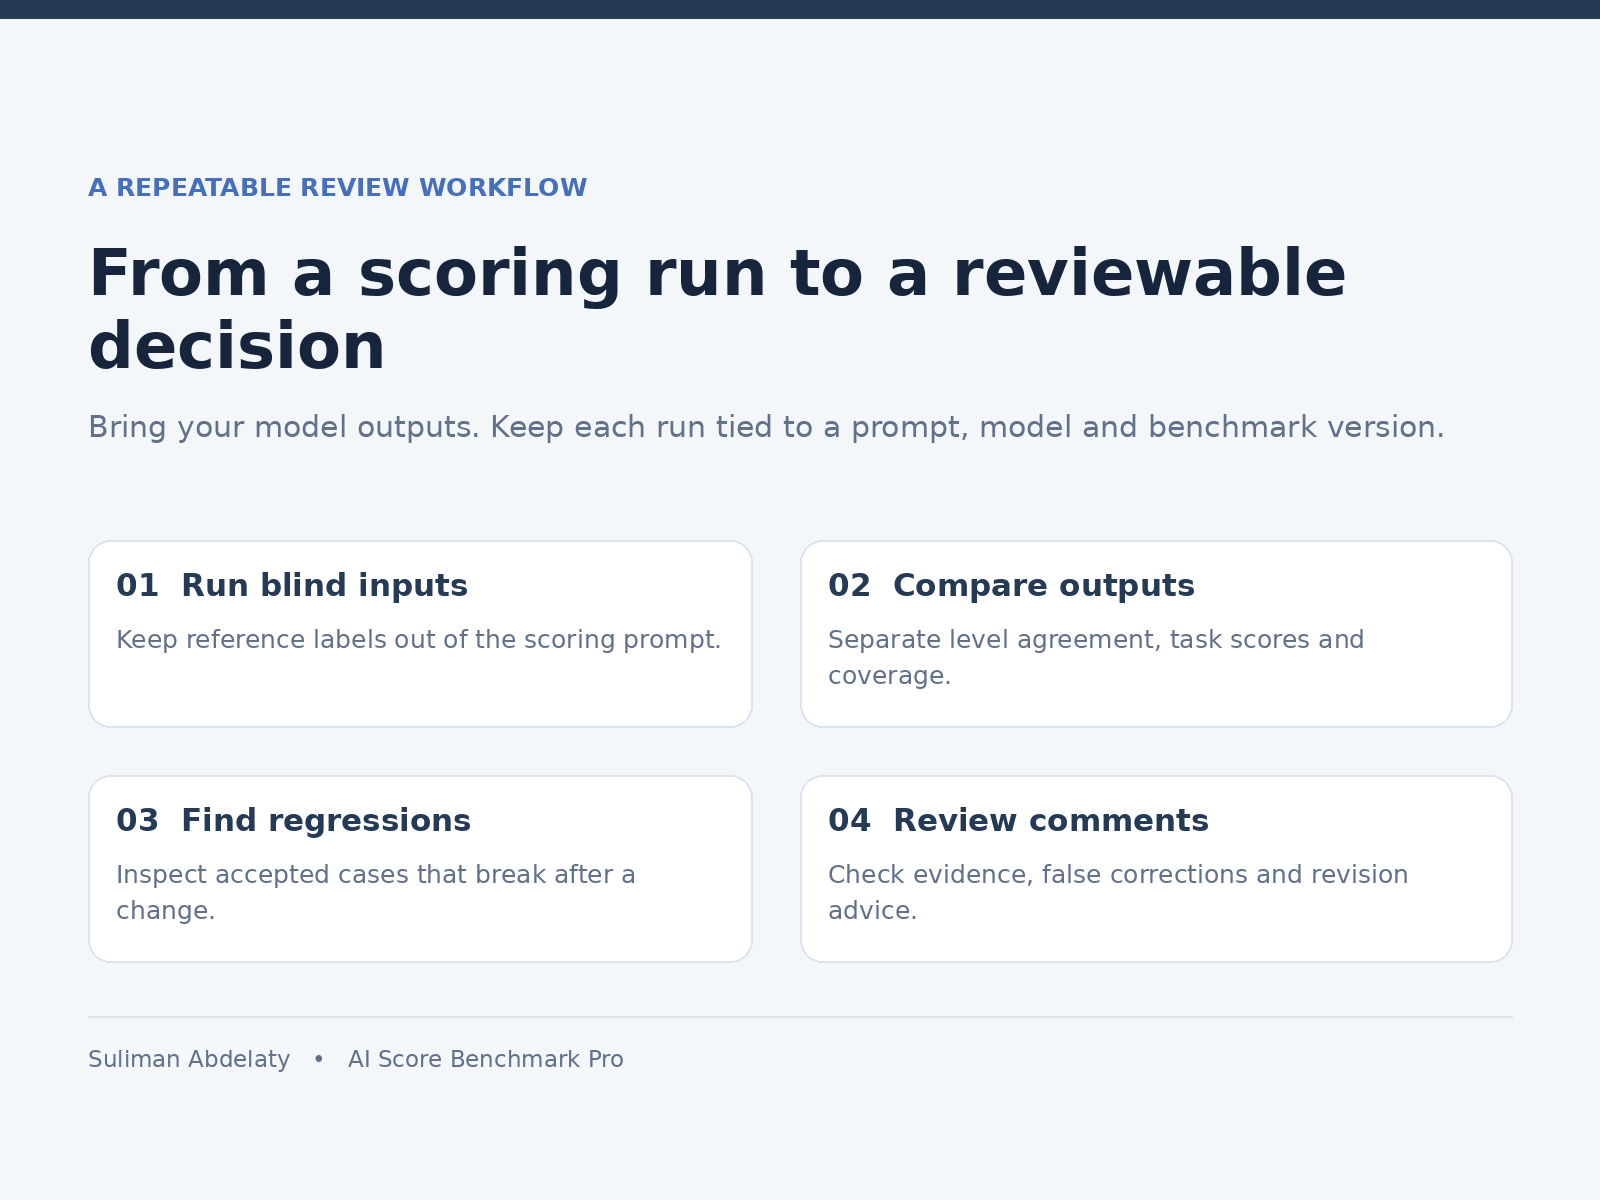
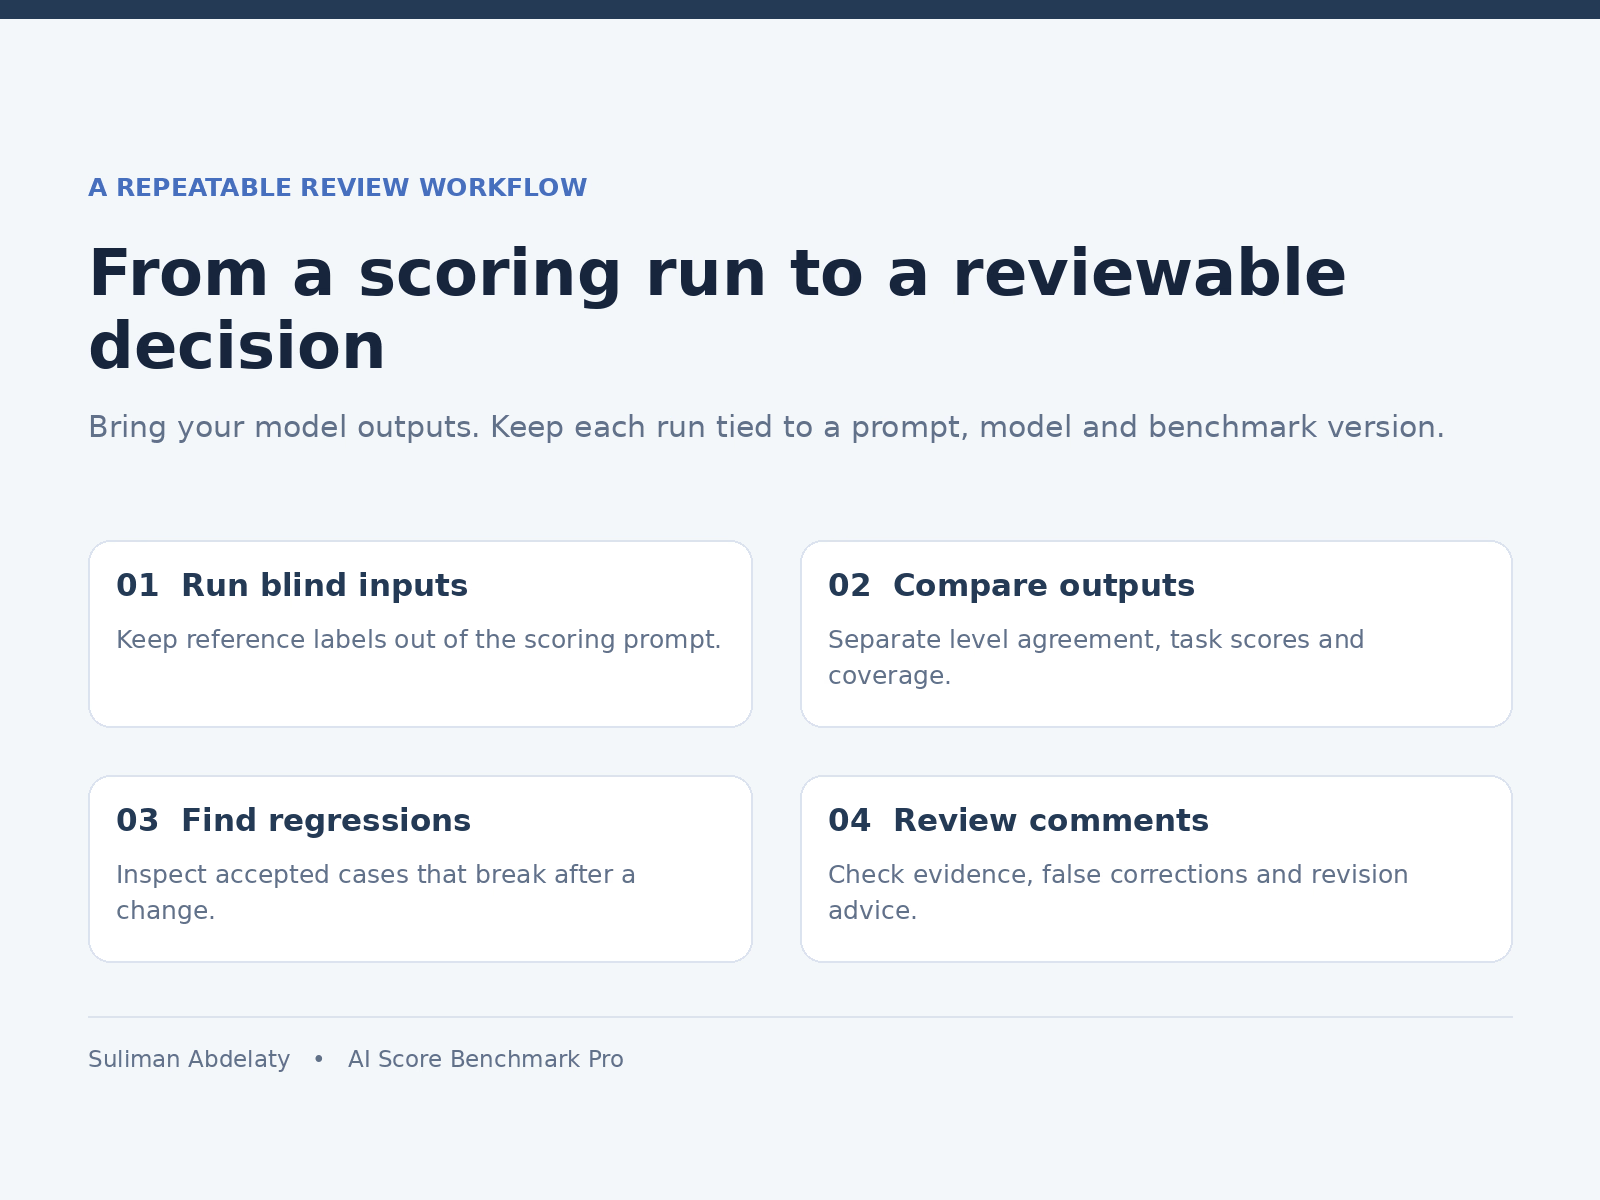
Run the supplied blind inputs through your model, import the outputs, and review scoring disagreements, criterion errors and individual regressions in an editable XLSX engine or an offline Python report.
WHAT YOU RECEIVE
60 core synthetic writing cases across A1-C2 design targets.
20 targeted edge cases, including fluent off-topic writing, false corrections, contradictory reasoning, valid dialects and embedded instructions.
12 extra robustness variants and 13 paired checks.
Five separate 0-5 criterion ratings, transparent rationales, selected error annotations and expected-feedback notes.
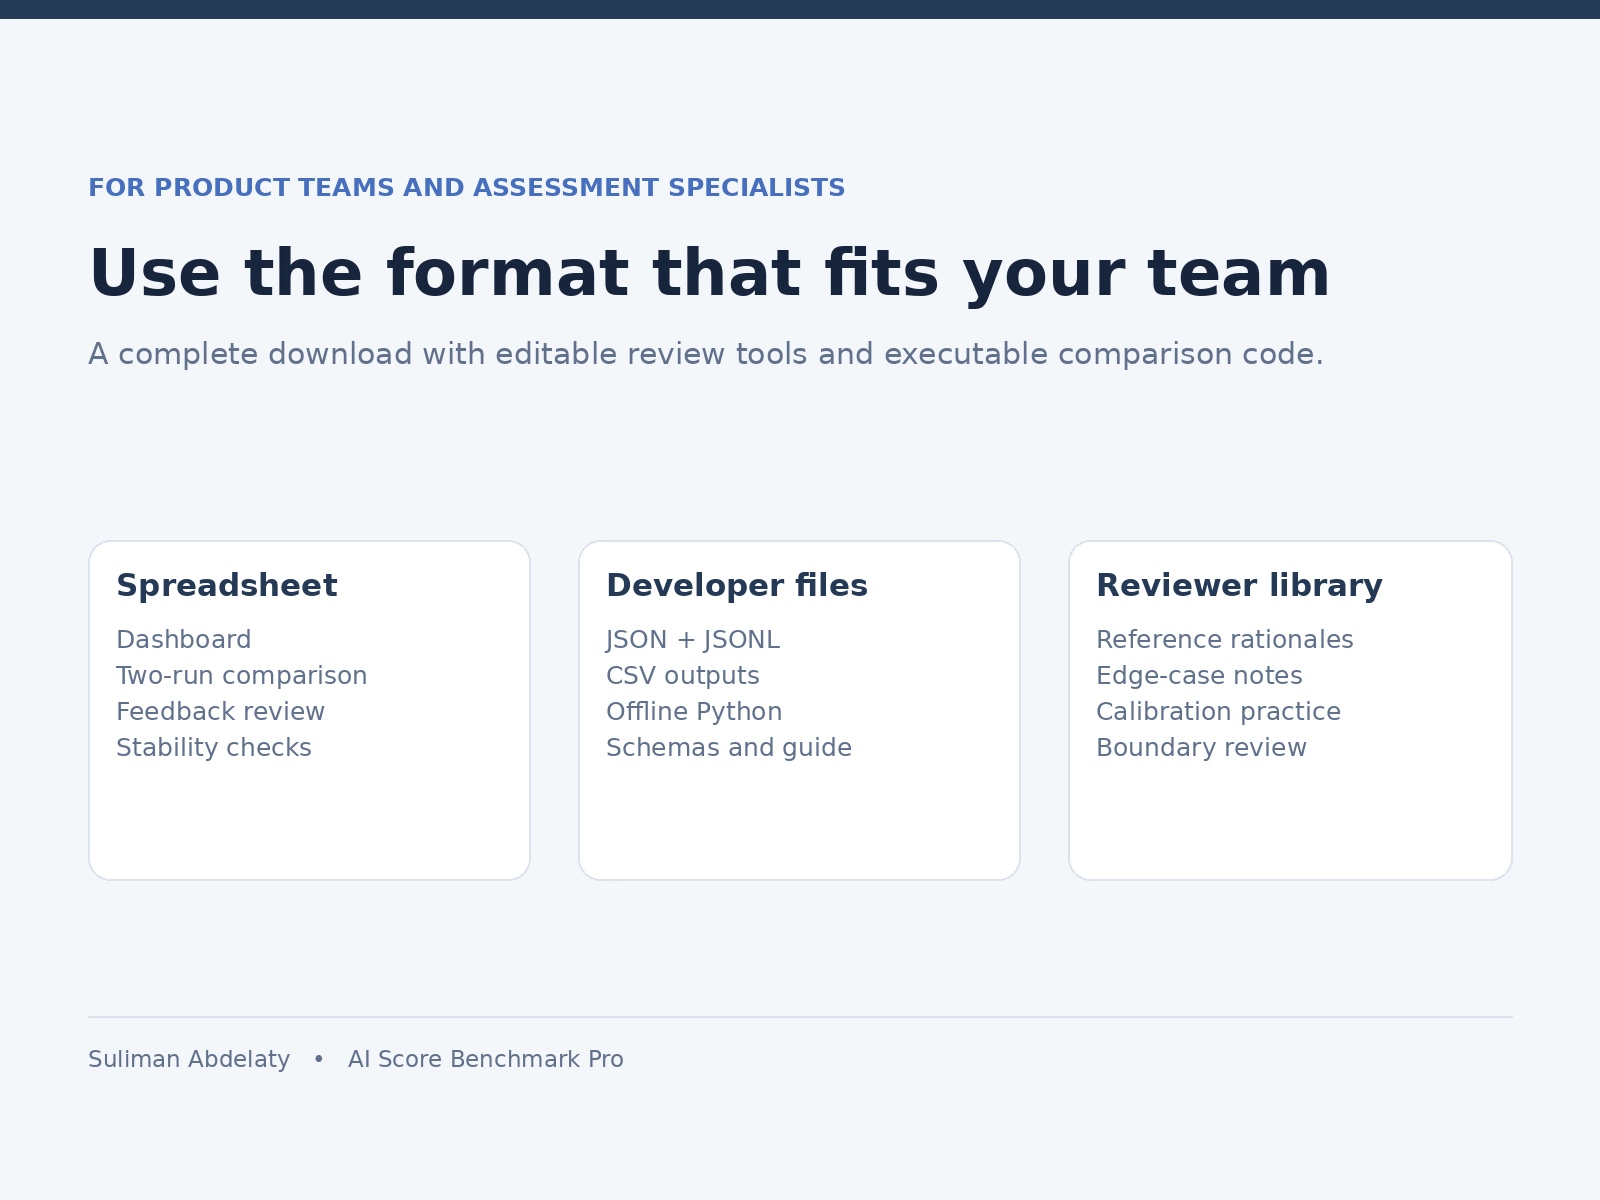
A two-run Excel dashboard, matched regression review and confusion matrices.
Manual feedback-quality and false-correction review tools, plus repeated-run stability checks.
16 selected boundary examples and 10 calibration exercises with a separate answer key.
XLSX, CSV, JSON and blind JSONL exports, output schemas, an offline Python evaluator and a local report viewer.
Buyer handbook, task/rubric guide, developer guide, commercial licence and a clearly labelled sample evaluation.
BUILT FOR REPEATED USE
Compare model versions or scoring prompts, inspect individual failures, preserve run metadata and use the builder forms to develop your own independently rated extensions.
REFERENCE STATUS
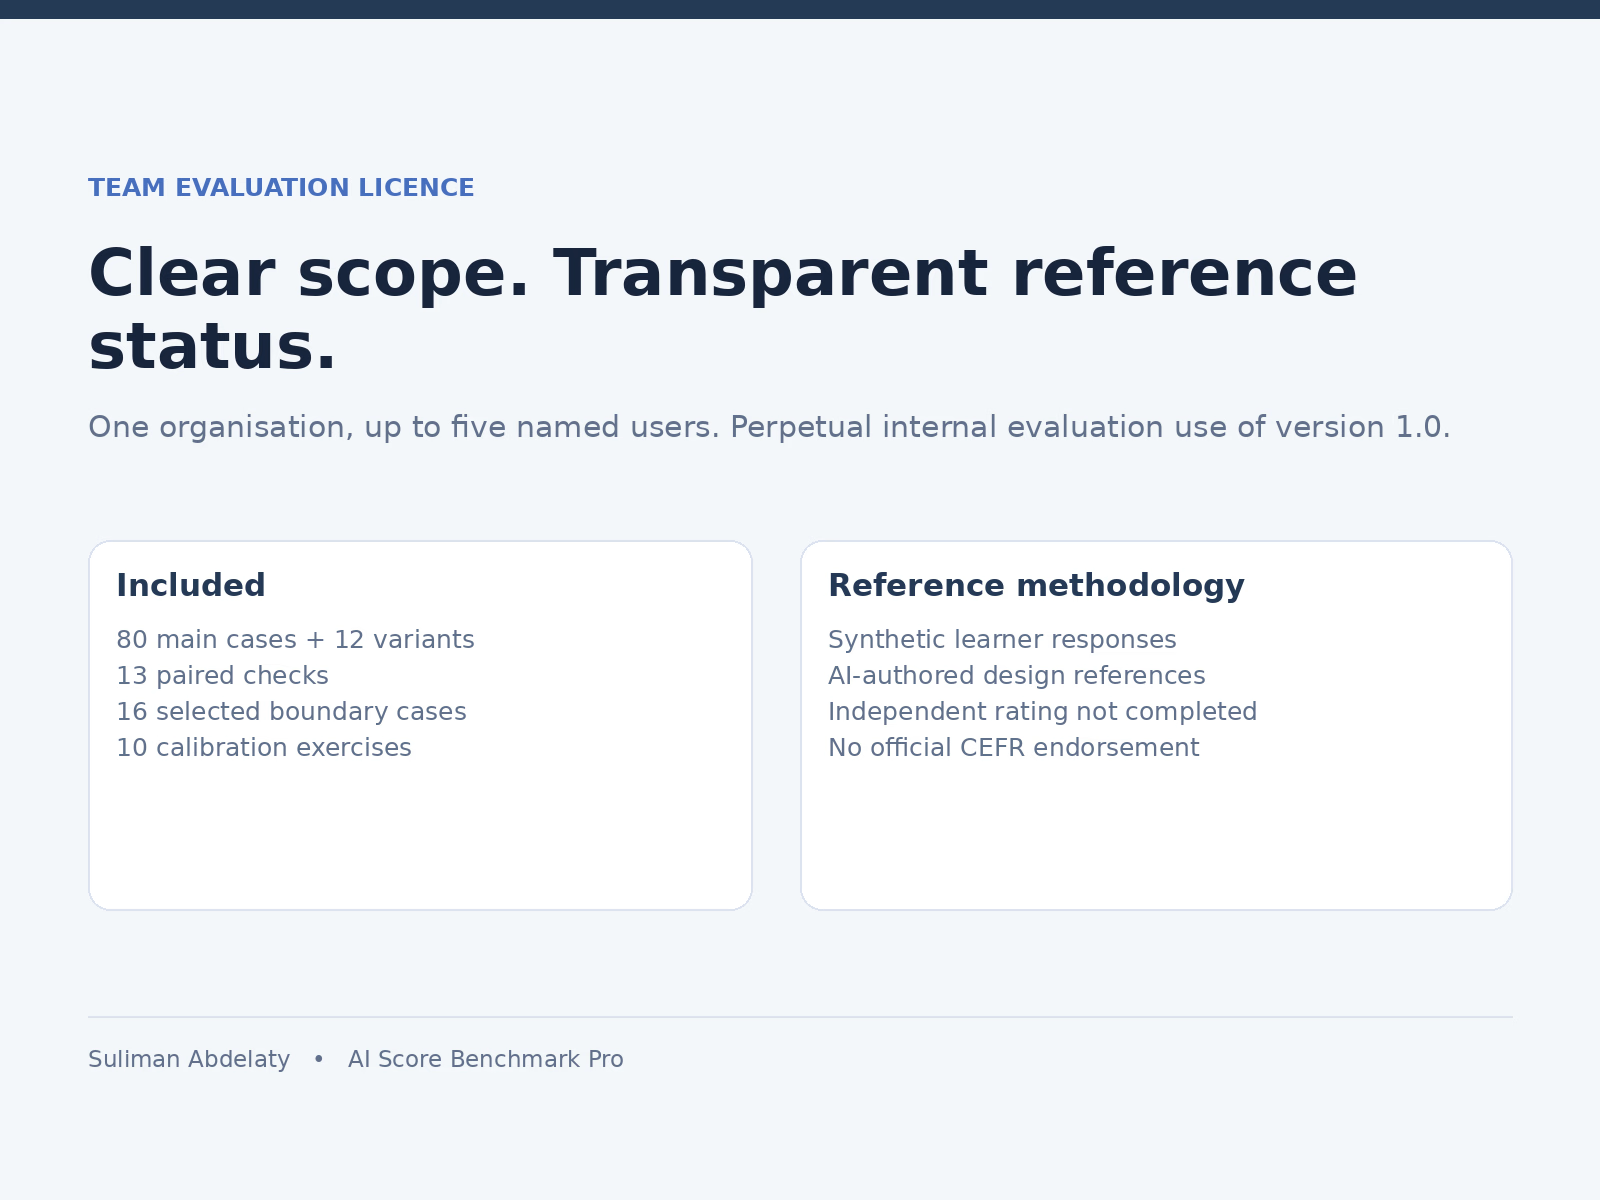
This is the Synthetic Development Edition. Responses and reference ratings are AI-authored provisional design material. Independent human rating has not been completed. It is intended for internal development, exploratory QA and calibration practice; it is not an operationally validated human benchmark or official CEFR assessment. Totals out of 25 do not convert directly into CEFR bands.
DELIVERY
One complete ZIP download. No hosted scoring service or AI subscription is included. Bring your own model outputs. Use an XLSX-capable spreadsheet application or Python 3.10+; the evaluator needs no third-party Python packages.
LICENCE
One organisation, up to five named internal users. Perpetual evaluation use of this delivered version. Internal prompt comparison and regression testing are permitted. Dataset resale, public redistribution and model-weight training/fine-tuning are excluded. See the included Commercial Licence for full terms.
Get it for$199.00
Tags
Quality Assurance
Artificial Intelligence
Product created by
Suliman Abdelaty London, UK
Suliman's other products
EnglishLevel Pro CEFR Placement Founding Pilot
$329.85
AI Score Benchmark Pro: Free Writing QA Preview
$0.00
Get it for$199.00
Tags
Quality Assurance
Artificial Intelligence
How does your AI writing scorer behave when an answer is fluent but off-topic, a valid phrase is flagged as an error, or a prompt update breaks a previously accepted case?
AI Score Benchmark Pro gives EdTech teams, assessment specialists and researchers a repeatable way to compare AI English-writing scores and feedback.
Run the supplied blind inputs through your model, import the outputs, and review scoring disagreements, criterion errors and individual regressions in an editable XLSX engine or an offline Python report.
WHAT YOU RECEIVE
60 core synthetic writing cases across A1-C2 design targets.
20 targeted edge cases, including fluent off-topic writing, false corrections, contradictory reasoning, valid dialects and embedded instructions.
12 extra robustness variants and 13 paired checks.
Five separate 0-5 criterion ratings, transparent rationales, selected error annotations and expected-feedback notes.
A two-run Excel dashboard, matched regression review and confusion matrices.
Manual feedback-quality and false-correction review tools, plus repeated-run stability checks.
16 selected boundary examples and 10 calibration exercises with a separate answer key.
XLSX, CSV, JSON and blind JSONL exports, output schemas, an offline Python evaluator and a local report viewer.
Buyer handbook, task/rubric guide, developer guide, commercial licence and a clearly labelled sample evaluation.
BUILT FOR REPEATED USE
Compare model versions or scoring prompts, inspect individual failures, preserve run metadata and use the builder forms to develop your own independently rated extensions.
REFERENCE STATUS
This is the Synthetic Development Edition. Responses and reference ratings are AI-authored provisional design material. Independent human rating has not been completed. It is intended for internal development, exploratory QA and calibration practice; it is not an operationally validated human benchmark or official CEFR assessment. Totals out of 25 do not convert directly into CEFR bands.
DELIVERY
One complete ZIP download. No hosted scoring service or AI subscription is included. Bring your own model outputs. Use an XLSX-capable spreadsheet application or Python 3.10+; the evaluator needs no third-party Python packages.
LICENCE
One organisation, up to five named internal users. Perpetual evaluation use of this delivered version. Internal prompt comparison and regression testing are permitted. Dataset resale, public redistribution and model-weight training/fine-tuning are excluded. See the included Commercial Licence for full terms.
Suliman's other products
EnglishLevel Pro CEFR Placement Founding Pilot
$329.85
AI Score Benchmark Pro: Free Writing QA Preview
$0.00
$199.00