

I recently fine-tuned the Mistral 7B Instruct model on a dataset of NDA (Non-Disclosure Agreement) documents — building an AI reviewer capable of identifying compliance issues and clause inconsistencies.
To make the model more accessible, I converted the trained weights to CPU-compatible files, allowing efficient inference without GPU requirements.
Model: Mistral 7B Instruct v0.1
Focus: Legal text review & semantic understanding
Tech: PyTorch, Transformers, Kaggle
Check out the full notebook here → [Kaggle Project Link (https://www.kaggle.com/code/karansingh123456/nda-reviewer-model-training)]
My Kaggle account here → Profile (https://www.kaggle.com/curiouscyborgs)
#AI #NLP #SentimentAnalysis #DeepLearning #CNN #LSTM #DataScience #GitHub
0
83
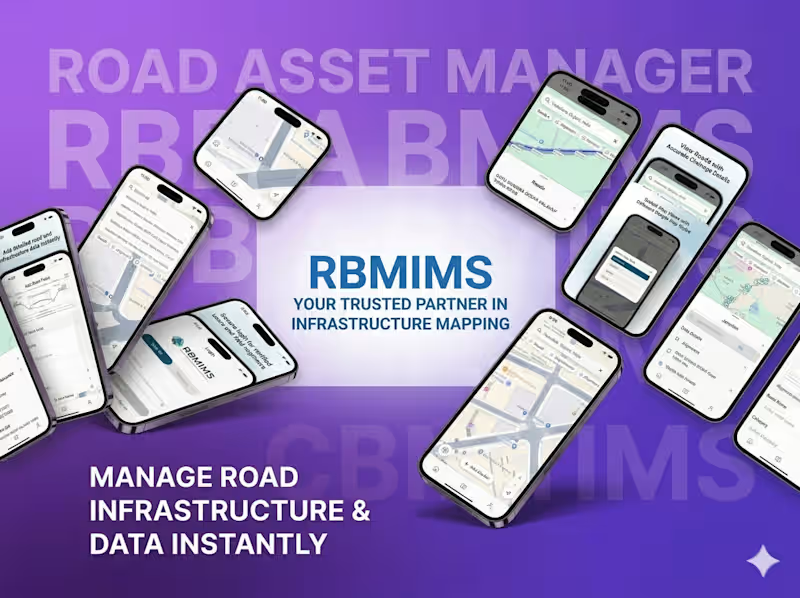
RBMIMS : (Geo Mapping)
◆ Context & Challenge
The client aimed to digitize and streamline road infrastructure data collection and management for government departments, engineers, and field surveyors.
The challenge was to:
‣ Replace manual and fragmented data collection processes
‣ Enable accurate, real-time geospatial data capture from field locations
‣ Ensure usability for on-ground teams working in diverse conditions
‣ Provide a centralized system for monitoring, validation, and approvals
◆ Approach & Solution
We developed RBMIMS (Road Building Mapping Information Management System), an intelligent geospatial platform designed to digitize infrastructure mapping and streamline field operations.
The solution leverages mobile-based data capture, GPS tracking, and structured workflows to enable efficient infrastructure monitoring and management.
◆ Key focus areas:
‣ Geospatial data collection and mapping
‣ Real-time GPS-based tracking and field data capture
‣ Structured workflows for infrastructure management
‣ Offline functionality for remote field usage
‣ Centralized system for monitoring and approvals
◆ Execution
‣ Designed and developed a mobile-first geospatial application for field teams
‣ Built backend systems for real-time data synchronization and storage
‣ Implemented GPS-based mapping and structured data collection forms
‣ Developed offline capabilities for uninterrupted field operations
‣ Created dashboards for centralized monitoring and approval workflows
◆ Outcome & Impact
RBMIMS transforms traditional infrastructure data collection into a digital, efficient, and scalable system.
‣ Improved accuracy and reliability of field data
‣ Reduced manual effort and data inconsistencies
‣ Enhanced visibility into infrastructure development processes
‣ Faster approvals and streamlined operational workflows
‣ Scalable solution for large-scale government deployment
0
71

A compliance RAG copilot for the EU AI Act and GDPR
Most AI tools answer every question. In compliance, a confident wrong answer is worse than none, because someone might act on it.
So I built a system designed to say "I don't know" when the law doesn't support an answer.
Ask a question in plain English and you get one of two things:
✅ An answer where every claim links to the exact Article or Recital it came from
🟠 An honest abstention that explains why the sources can't support an answer
How it works
• A six-step LangGraph agent: plan → retrieve → rerank → generate → critique → human check
• The critic can send a weak draft back for better evidence, with hard caps on retries and token spend
• Citations are checked against the sources the model actually saw. Invented ones are removed, not trusted
• 1,437 passages from the AI Act and GDPR, with embeddings computed locally on CPU
Measured, not claimed (37-question golden set)
• 36/37 correct abstention decisions, 0 false answers
• 0.99 faithfulness to sources
• 0.97 recall@5
Runs on $0/month: free-tier hosting end to end (Cloud Run, Vercel, Neon, Upstash), with provider fallback on every model call.
Stack: Python · FastAPI · LangGraph · Postgres + pgvector · Next.js · AI SDK
🔗 Try it live: ai-lab-web-ten.vercel.app (http://ai-lab-web-ten.vercel.app)
0
172


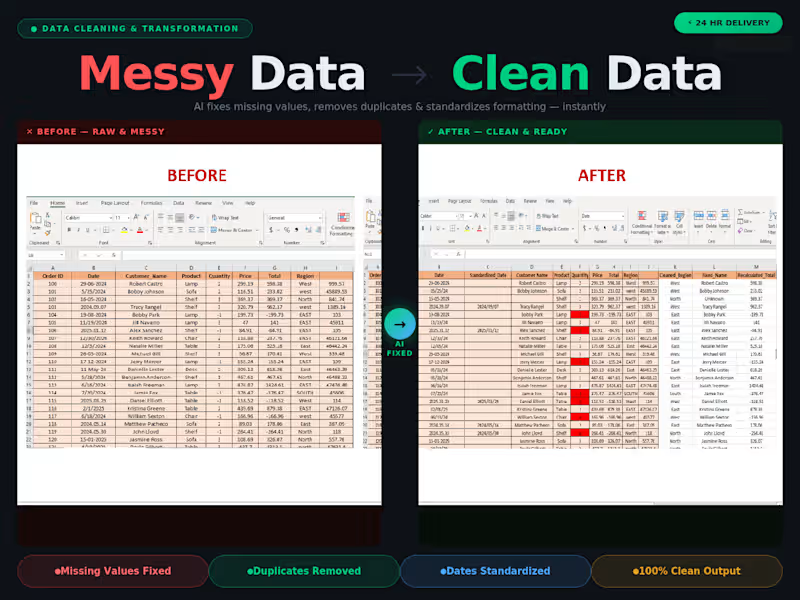
I specialize in data cleaning and preprocessing, ensuring your spreadsheets or databases are accurate, well-formatted, and ready for analysis or reporting.
What Ill do for you:
Remove duplicates, nulls, and inconsistencies
Standardize date, text, and numeric formats
Fix spelling/case issues
Split/merge columns (e.g., names, addresses)
Convert file formats (CSV Excel SQL)
Python or SQL-based advanced cleaning (if required)
Supported formats: Excel, CSV, Google Sheets, SQL dumps
Clean, fast & confidential service
100% satisfaction guaranteed
Message me before ordering so I can understand your dataset and goals!
0
628
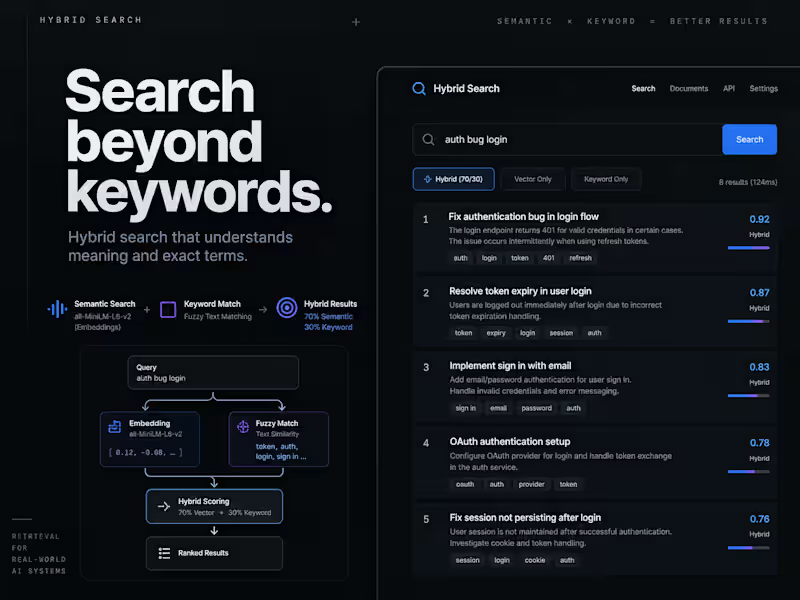
Hybrid Semantic Search Engine
Keyword search misses results that mean the same thing in different words. Pure vector search misses exact matches.
I built a hybrid search engine that combines both. Text is embedded with the all-MiniLM-L6-v2 sentence model and indexed in FAISS, and each query blends vector similarity with fuzzy text matching (weighted 70/30), so results match on meaning and on exact terms.
Built as a FastAPI backend with a React frontend, packaged with Docker so it runs with one command.
What this shows: I understand how retrieval works under the hood, the same retrieval that powers RAG chatbots, and where it fails.
0
19